
OWASP LLM05:2025 secure-handling checklist
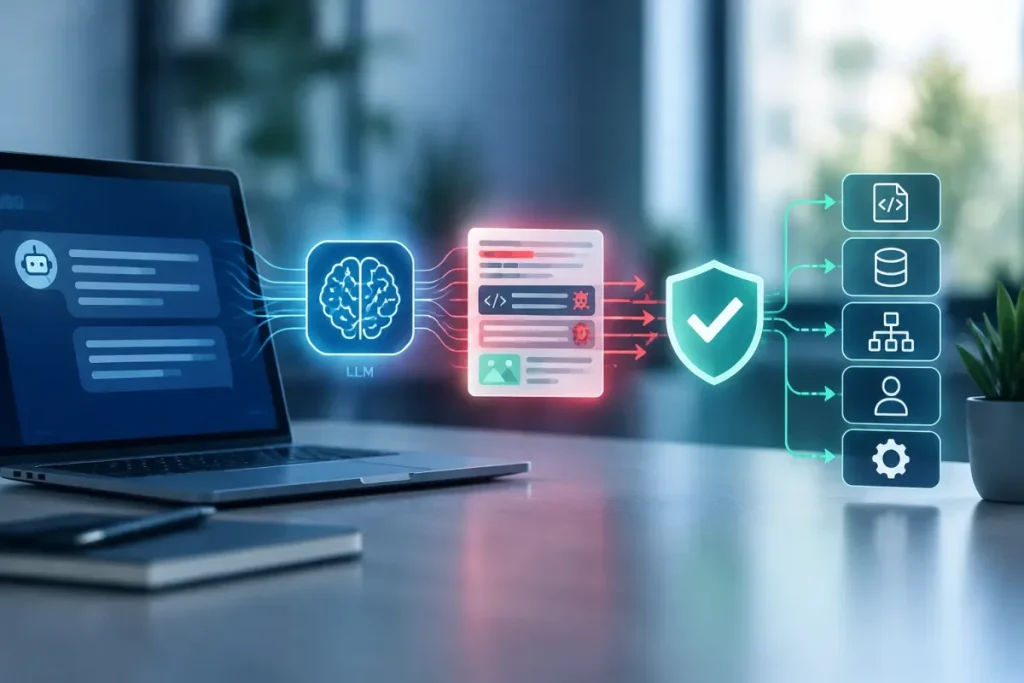
- Improper LLM output handling, designated OWASP LLM05:2025, occurs when an application fails to properly validate, sanitize, encode, authorize, or otherwise safely handle LLM-generated output before passing it to a user interface or downstream system. Because model output can be influenced by attackers, treating it as trusted data can enable vulnerabilities such as XSS, injection, code execution, SSRF, data leakage, or unauthorized actions. Treat LLM output as untrusted input and apply destination-specific validation and encoding, safe APIs or parameterized queries, authorization checks, and least privilege.
- Render text safely and use context-appropriate output encoding or sanitization; do not insert untrusted model output into HTML or other interpreters directly.
- Use parameterized database queries and fixed, allowlisted functions or tool schemas instead of concatenating model output into SQL, shell commands, or executable code.
- Validate tool calls, URLs, arguments, and structured output against strict schemas and business rules before execution.
- Apply authentication, authorization, approval gates, and least-privilege permissions to downstream actions.
Improper LLM output handling, designated OWASP LLM05:2025, occurs when an application fails to validate, sanitize, encode, authorize, or safely process LLM output before sending it to a user interface or downstream system. Treat it as untrusted input because unsafe handling can enable downstream security vulnerabilities.
What is Improper LLM Output Handling?
LLM05:2025 Improper Output Handling is the failure to safely process model-generated content before it reaches a user, browser, database, shell, API, tool, workflow, or another application component. For broader coverage of related risks and mitigations, consult the OWASP Top 10 for LLM Applications.
The decisive rule is simple: LLM output is not trusted internal application data. It must be handled like any other untrusted input, with controls matched to the destination that consumes it.
The impact depends on how and where the output is used. A response displayed as plain text requires different controls from one inserted into HTML, used in a database query, passed to a shell, or converted into a privileged tool call. This is not merely a model-accuracy problem. The vulnerability occurs when an application propagates or processes generated content unsafely.
Why LLM output is untrusted
An LLM can be influenced by direct prompts, prompt injection, retrieved content, external data, and other inputs. An attacker does not always need to control the final response directly. Influencing the model may be enough if the application automatically renders, executes, stores, or forwards what it produces.
The model is not a security boundary. Text that appears harmless can become HTML, SQL, a shell command, a URL, a tool argument, or a workflow instruction when another component interprets it. Plausibility or apparent helpfulness does not make generated content safe.
Retrieved or external content creates the same concern. If source content is misleading, tampered with, or otherwise influences retrieval, it can contribute to unsafe output. Source authentication and integrity, retrieval behavior, and model-driven actions should therefore be included in monitoring and threat modeling.
How the vulnerability works
- An attacker-controlled or indirectly influenced input reaches the application through a prompt, retrieved content, or external data.
- The model produces output influenced by that input.
- The application treats the output as trusted instead of untrusted data.
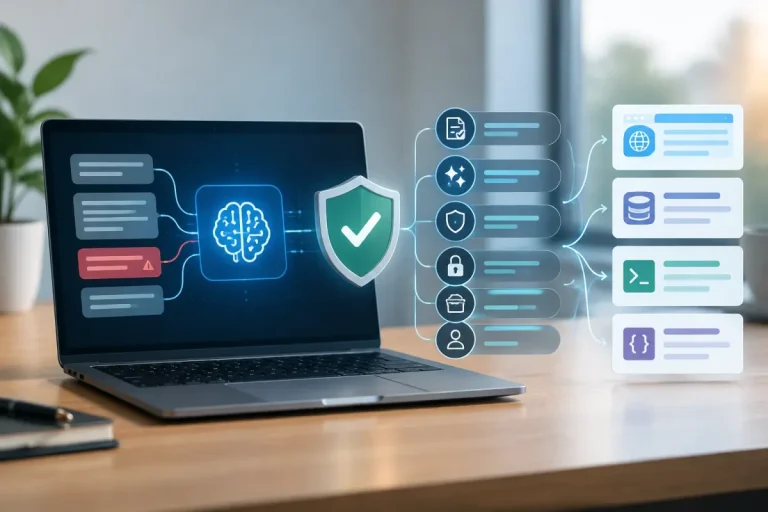
- The output is rendered, stored, executed, or forwarded without suitable validation and destination-specific controls.
- The downstream component interprets it in a way that creates a security impact.
For example, a prompt-injected summarizer could be influenced to collect sensitive content and send it through a downstream request. A browser could interpret generated markup as executable content. A database layer could receive model-derived text as part of raw SQL. A tool-enabled agent could use an unvalidated URL or argument to perform an unauthorized action.
These cases share a common cause: unsafe output propagation. Every response is not malicious, but an application becomes vulnerable when it gives generated output inappropriate trust or privilege.
Attack paths by downstream destination
Browser output and XSS
If model-generated HTML, JavaScript, Markdown, or chatbot content is inserted into a browser without suitable controls, it can create cross-site scripting (XSS) risk. Using innerHTML with untrusted model output can cause the browser to interpret that output as markup.
Rendering an intended plain-text response with textContent is safer for that specific use case, but it is not a universal fix. The application still needs handling appropriate to the content format and rendering context.
Databases and SQL injection
Free-form model output must not determine raw SQL structure. Concatenating LLM-derived text into a query can create SQL injection risk or unintended data access.
Keep query structure under application control and pass model-derived values through parameterized queries or prepared statements. Sanitization alone is not a substitute for parameterization.
Shells, execution, and code
Passing generated commands or code to a shell, exec, eval, or a similar mechanism can create command injection or code execution risk.
A safer design exposes only fixed, allowlisted operations through controlled interfaces rather than permitting unrestricted execution. When execution is necessary, restricted tools and isolated environments can limit the impact of a failure.
APIs, tools, URLs, and connected services
LLM output can become a tool call, URL, path, API argument, or workflow instruction. If these values are not validated and authorized, the application may make unauthorized requests, reach an unintended service, contribute to SSRF, abuse a privileged function, or expose sensitive data.
| Destination | Potential impact | Primary control |
|---|---|---|
| Browser rendering | XSS or unsafe interpretation of generated content | Safe text rendering plus context-aware encoding or sanitization |
| Database query | SQL injection or unintended data access | Parameterized queries or prepared statements |
| Shell or code execution | Command injection or code execution | Fixed, allowlisted operations and isolated execution |
| API, URL, or tool | SSRF, privilege abuse, data leakage, or unauthorized actions | Strict schemas, validation, authorization, and restricted tools |
How to prevent improper output handling
Use context-specific validation, sanitization, and encoding
There is no single sanitizer that makes every destination safe. Validation, sanitization, and encoding must match the destination and its interpreter. For a practical implementation guide, see secure LLM outputs.
Render ordinary responses as text when text is the intended result. When formatted content is required, use an appropriate strategy for that browser context. Do not insert untrusted model output directly into HTML or another interpreter.
For structured responses, enforce strict schemas for required fields, data types, allowed values, ranges, and business rules. Syntactically valid output can still request an unauthorized or unsafe action.
Use safe database and tool interfaces
Use parameterized queries or prepared statements, and keep query structure and accessible data under application control. Do not allow free-form model output to define SQL syntax.
For tools and functions, expose fixed, allowlisted operations rather than unrestricted execution. Validate tool names, URLs, arguments, paths, and resource identifiers before performing an action. Safe APIs and explicit function mappings are stronger controls than concatenating model output into SQL, shell commands, or executable code. For examples of failures involving legitimate but unsafe tool use, see AI agent tool misuse.
Enforce authorization and least privilege
Output handling must include authorization, not just filtering. Authenticate the requesting user, enforce user-scoped permissions, and require an approval gate when a high-impact action should not happen automatically. For a deeper treatment of identities and authorization in AI systems, see IAM for AI applications.
Give tools and connected services only the permissions they need. Least privilege, restricted tools, limited credentials, and isolated execution reduce the impact when output is malicious, malformed, or simply wrong. These controls complement validation and safe interfaces; they do not replace them.
Monitoring and testing
Log model-driven tool calls, destinations, authorization decisions, blocked actions, and execution outcomes. Maintain audit trails for actions that change data or interact with connected services. For guidance on what to observe at runtime, see AI security monitoring.
Test the complete data flow rather than only the chat interface:
- Inventory every output sink: browsers, databases, files, shells, APIs, URLs, tools, workflows, and connected services.
- Map each interpreter: HTML, SQL, a command shell, a URL client, a structured API, or another execution context.
- Test negative cases: unexpected types, malformed structures, disallowed values, unauthorized tools, invalid URLs, unsafe paths, and excessive permissions.
- Test prompt-injection-driven abuse: evaluate unusual, manipulated, malformed, or influenced responses and their downstream effects.
- Threat-model the full chain: include prompts, retrieved content, external data, model output, permissions, and possible data flows.
- Review isolation and monitoring: confirm that tools have only the access required and that rejected outputs and blocked actions are visible to defenders.
Monitoring and anomaly detection can help identify unexpected destinations, unusual tool usage, repeated rejected requests, or retrieval behavior that contributes to unsafe results. Human review is appropriate for high-impact actions where automated execution could cause significant harm.
Improper Output Handling versus Overreliance
Improper Output Handling concerns the unsafe processing or propagation of model output. The key question is whether the application renders, stores, executes, or forwards generated content without appropriate controls.
Overreliance concerns dependence on the output’s accuracy or appropriateness. An application can overrely on a model even when it safely renders the response as text, and it can have improper output handling even when the response is factually correct. The risks can coexist, but they require different controls.
Concise secure-handling checklist
- Treat all LLM output as untrusted input.
- Validate, sanitize, and encode it for the specific destination.
- Use parameterized queries and constrained, allowlisted tools or functions.
- Enforce authentication, authorization, least privilege, and approval controls.
- Isolate execution, monitor model-driven actions, and test every downstream integration.
OWASP LLM05:2025 is a data-flow security problem. The reliable approach is to assume generated output is untrusted, keep interpreters and permissions under application control, and apply defenses appropriate to every destination.