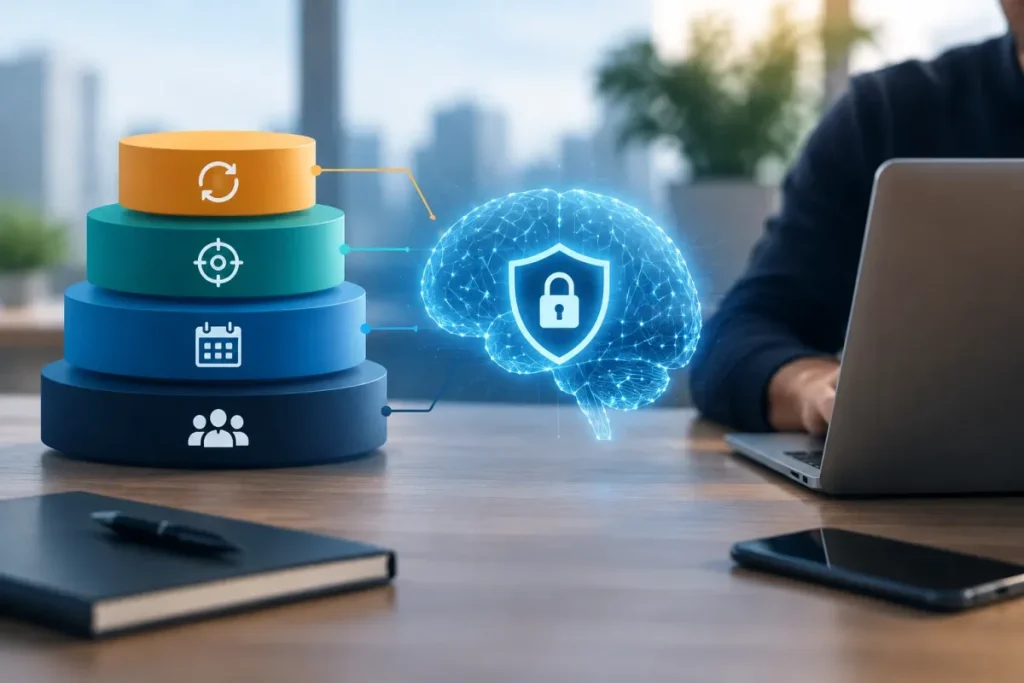

Recommended AI penetration-testing cadence
- Use a risk-based layered schedule: continuously or after significant changes for automated and targeted checks, quarterly to monthly for structured reviews when risk or change velocity warrants it, and at least annually for a comprehensive human-led penetration test. Retest immediately after major AI-system changes or security incidents.
- Integrate automated AI-security checks into CI/CD, scheduled builds, or continuous monitoring where feasible.
- Run targeted testing immediately after major code, prompt, model, RAG, tool, provider, embedding, architecture, or integration changes.
- Schedule structured red-team or technical reviews quarterly or more frequently for rapidly evolving or high-risk systems.
- Complete a full-scope manual penetration test at least annually and after significant incidents or redesigns.
Use a risk-based layered schedule: run automated and targeted checks continuously or after significant changes, conduct quarterly-to-monthly structured reviews when risk or change velocity warrants them, and complete a comprehensive human-led penetration test at least annually. Retest immediately after major AI-system changes or security incidents.
How often should you penetration test an AI application?
There is no single interval for every AI application. For most organizations, at least one comprehensive human-led penetration test each year is the baseline. Supplement it with automated checks, targeted retesting, and more frequent reviews when the application changes quickly, handles sensitive data, has complex integrations, or faces significant threat exposure.
An annual test alone may not be enough for a high-risk, regulated, complex, or rapidly changing system. Conversely, continuous testing does not mean performing a complete manual penetration test every day. A practical program separates automated checks, event-driven testing, structured reviews, and full expert-led assessments.
A practical AI penetration-testing cadence
| Testing layer | Recommended timing | Purpose |
|---|---|---|
| Automated checks | Continuously through CI/CD, scheduled builds, or monitoring where feasible; repeat after material changes | Find issues early in code, APIs, configurations, AI features, integrations, and security controls |
| Targeted retesting | After a specific component, workflow, model, provider, or control changes | Validate the changed attack surface without automatically requiring a full-scope assessment |
| Structured technical or red-team reviews | Biannually for some moderate-risk environments; quarterly to monthly when risk or change velocity warrants it | Assess broader attack paths, access controls, integrations, AI workflows, and application behavior |
| Comprehensive human-led penetration test | At least annually, plus after major redesigns or significant incidents | Evaluate exploitability, authorization, business logic, impact, and relevant AI-specific risks |
Continuous automated and targeted checks
Integrate automated AI-security checks into CI/CD pipelines, scheduled builds, or continuous monitoring where practical. Run them as code, APIs, infrastructure, or relevant AI features change. Targeted testing provides earlier feedback when a particular component changes instead of waiting for the next scheduled review. For broader guidance on runtime visibility, see AI security monitoring.
These checks are useful for frequent releases and repeatable validation, but they do not replace expert judgment about exploitability, attack paths, authorization, business impact, or interactions between application controls and AI behavior.
Biannual, quarterly, or monthly reviews
A biannual penetration test can suit a moderate-risk application that changes regularly but lacks the velocity, sensitivity, complexity, or exposure of a high-risk system. It is a risk-based option, not a universal requirement.
Use structured technical or red-team reviews quarterly, or more often, when an application is highly exposed, complex, regulated, high-risk, or changing rapidly. A monthly schedule may fit some especially dynamic environments, but it is not mandatory for every AI application. These reviews can combine focused expert assessment, automated checks, and targeted validation rather than requiring a full manual test every month.
At least annual comprehensive human-led testing
Plan a comprehensive human-led penetration test at least annually as the baseline for most organizations and AI applications. Human testers can connect weaknesses across application behavior, identity and access controls, integrations, model-related functionality, and business logic in ways automated checks may not.
The annual assessment should cover conventional web and API security, authentication, authorization, infrastructure, integration paths, and relevant AI-specific functionality. Scope may differ depending on whether the application uses a provider API, a self-hosted model, or a fine-tuned or self-trained model.
When to retest outside the calendar
Retest whenever a material change could alter the application’s attack surface, trust boundaries, data flows, model behavior, or security controls. These changes do not automatically require a full-scope manual assessment, but they do require proportionate automated, targeted, or expert-led testing.
- Code and architecture: Major releases, redesigns, infrastructure changes, API changes, and changes to service boundaries.
- Prompts and models: Material changes to system prompts, model configurations, models, or providers that could affect request processing or data handling.
- RAG and embeddings: Changes to retrieval-augmented generation workflows, embeddings, knowledge sources, or related data flows that affect behavior or access.
- Tool calling and integrations: New or changed tools, plugins, external services, integrations, or agent workflows that expand what the application can access or do.
- Identity and security controls: Changes to authentication, authorization, secrets management, network controls, or other security mechanisms.
Different implementation types, different testing emphasis
A provider API assessment may emphasize API-key protection, unauthorized access, data handling, and integration controls. A self-hosted model brings more of the surrounding infrastructure, deployment, and access boundary into scope. Fine-tuned or self-trained models may require additional attention to training-data risks and leakage alongside normal web, API, and authorization testing.
These differences affect scope and may affect frequency, but they do not create separate universal schedules. Apply the same risk-based baseline: continuous or event-driven checks where feasible, structured reviews when warranted, and a comprehensive human-led test at least annually.
Incidents, vulnerabilities, and remediation
Perform additional testing after a breach, security incident, critical vulnerability, or significant redesign. After remediation, conduct targeted retesting to verify the fix and check for new weaknesses. This work supplements the regular biannual, quarterly, or annual schedule.
How risk determines testing frequency
Use these factors to decide whether the annual baseline is enough or whether the application needs biannual, quarterly, monthly, or continuous testing:
- Deployment velocity: Frequent releases create more opportunities for security-relevant behavior to change and support more frequent automated checks.
- Data sensitivity: Confidential, personal, financial, healthcare, or otherwise sensitive data generally warrants stronger and more frequent validation.
- System complexity: Multiple models, providers, APIs, tools, retrieval systems, data stores, and identity boundaries create more paths to assess.
- Regulatory and contractual obligations: Applicable requirements can establish minimum expectations but do not create one universal AI-testing cadence.
- Threat exposure: Internet-facing systems, broadly accessible applications, and systems with valuable data or powerful tool access may justify more frequent reviews.
- Impact of failure: Greater business, safety, privacy, or operational impact makes an annual point-in-time assessment less suitable as the only control.
Higher-risk or rapidly evolving applications may need continuous automated checks plus quarterly or monthly structured reviews. Moderate-risk applications may use biannual reviews, while lower-change applications may use targeted checks when changes occur and a comprehensive annual assessment, provided that risk and applicable obligations support that approach. For a structured way to evaluate these factors, see an AI security risk assessment.
Automated checks versus expert-led penetration testing
Automated testing supplements, rather than replaces, human-led penetration testing. Automation is suited to repeatable checks during development and deployment, monitoring for known weaknesses, and validating selected security properties after changes.
Expert-led testing remains important for determining whether weaknesses can be chained into a meaningful attack, whether authorization logic is sound, how business logic can be abused, and what the practical impact would be. It also helps assess interactions between conventional application controls and AI-specific behavior.
Vulnerability scanning is narrower than penetration testing. Scanning identifies known issues and configuration problems, while penetration testing evaluates exploitability, attack paths, authorization logic, business logic, and impact. Both can support a layered program, but a scan is not a replacement for a penetration test. For a comparison of complementary scanning and adversarial-testing approaches, see AI red teaming and vulnerability scanning.
Compliance and broader testing scope
Compliance obligations may influence testing frequency, but they should be treated as minimum expectations rather than the strongest possible security schedule. The applicable requirement depends on the organization, application, data, contracts, and regulatory context. No single framework establishes one universal interval for every AI application.
Where risk exceeds the compliance minimum, use the stronger risk-based schedule and document how it reflects release velocity, data sensitivity, system complexity, threat exposure, and material changes.
Adding AI capabilities also does not remove the need to test conventional web, API, authentication, authorization, and application vulnerabilities. Address relevant AI-specific concerns, such as prompt injection, data leakage, and data poisoning, when they apply to the system’s design and data flows. For safeguards focused specifically on this risk, see how to prevent LLM data leakage.
Practical minimum schedule
- Run automated or focused checks continuously through CI/CD or monitoring where feasible.
- Retest after material changes to code, prompts, models, RAG workflows, tool calling, embeddings, providers, integrations, architecture, or security controls.
- Conduct biannual reviews for moderate-risk environments when appropriate, or quarterly-to-monthly structured reviews when risk, deployment velocity, sensitive data, complexity, or threat exposure warrants them.
- Complete at least one comprehensive human-led penetration test every year.
- Test promptly after incidents, critical vulnerabilities, major redesigns, and remediation.
For an AI application, use continuous or event-driven checks where feasible, add biannual, quarterly, or monthly reviews according to risk and change velocity, and maintain at least an annual comprehensive human-led penetration test. Major changes and incidents can require testing sooner.