

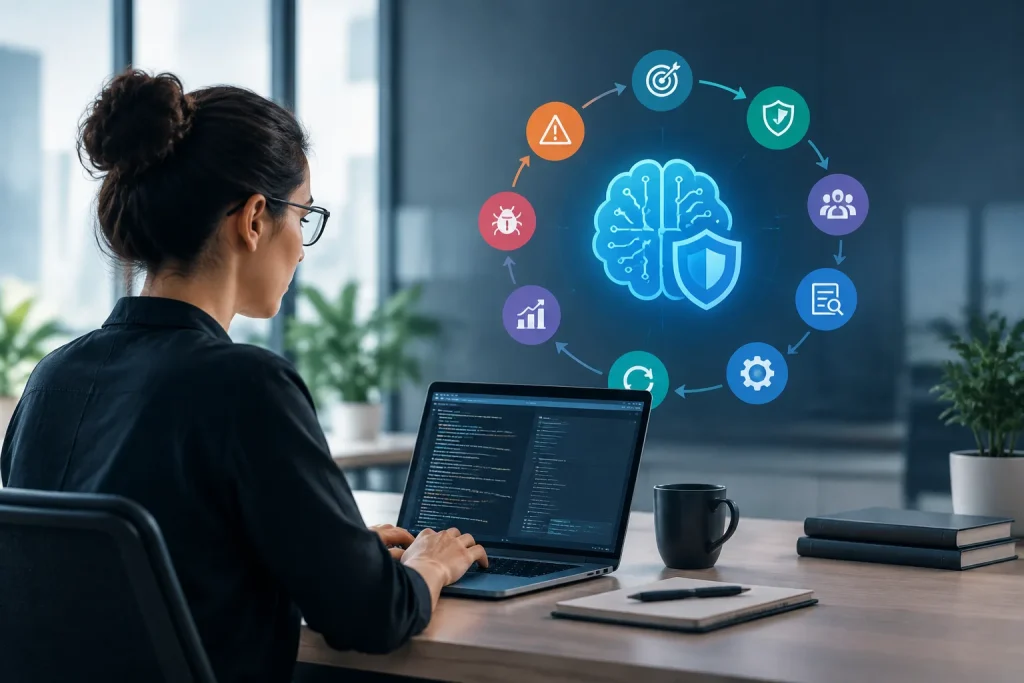

AI red teaming program lifecycle
- Build the program as a governed, continuous lifecycle: define scope and authorization, inventory the AI attack surface and threat model, assemble multidisciplinary expertise, create risk-based test plans, run manual and automated adversarial tests, demonstrate and prioritize real-world impact, report reproducible findings, remediate, and continuously retest after model, prompt, data, or tool changes.
- Start with an authorized pilot focused on one defined AI application and its highest-risk workflows.
- Combine manual expert probing with automated evaluation/red-teaming frameworks to improve coverage and repeatability.
- Prioritize findings by business and safety impact, such as data leakage, unauthorized actions, harmful outputs, prompt injection, privilege escalation, or agent/tool misuse.
- Validate mitigations and rerun the relevant test suite whenever models, prompts, retrieval data, tools, or integrations change.
Build the program as a governed, continuous lifecycle: define scope and authorization, inventory the AI attack surface, threat-model it, assemble expertise, test, report, remediate, and retest.
Start with an authorized pilot covering one defined AI application and its highest-risk workflows. Establish written rules of engagement before testing, then expand from repeatable assessments to automated regression testing and broader organizational governance.
What an AI red teaming program covers
AI red teaming is systematic adversarial evaluation of AI models and applications to identify vulnerabilities, unsafe behavior, misuse risks, and other failure modes. A program is more than isolated jailbreak experiments: it connects testing to threat modeling, ownership, remediation, and continuous validation.
The assessment must cover the full AI application stack, not only the base model:
- Models, applications, user interfaces, prompts, and orchestration logic
- Training or retrieval data, data boundaries, output handling, and privacy controls
- RAG pipelines, ingestion paths, retrieval permissions, and vector stores
- APIs, tools, plugins, agents, memory, credentials, and permissions
- Downstream applications, business workflows, and external integrations
Assess security, safety, privacy, reliability, and misuse risks. A model may behave acceptably in isolation while the surrounding application exposes sensitive data, grants excessive tool access, or passes unsafe output into a consequential workflow. For a focused treatment of unsafe agent tool use, see AI agent tool misuse.
1. Define the charter, authorization, and rules of engagement
Set governance before any adversarial assessment begins. The charter should state why the organization is testing, which risks matter most, who owns the system, and how findings move from discovery to remediation or formally accepted residual risk.
Start with an authorized pilot
Choose one AI application and its highest-risk workflows. Document intended users, protected assets, deployment environments, interfaces, excluded systems, and accountable owners. Assign responsibility for system ownership, testing, engineering remediation, risk decisions, and stakeholder communications.
Prioritize consequences such as sensitive-data exposure, unauthorized business actions, harmful content, privilege abuse, unreliable decisions, and agent misuse. The objective is to reduce meaningful business and safety risk, not to collect the most creative attacks.
Write the rules of engagement
Obtain written authorization from the system owner or another accountable authority. Define permitted systems, test accounts, environments, data, interfaces, approval gates, escalation routes, reporting expectations, and who can accept residual risk.
Test only systems the organization owns or has explicitly authorized. Use non-production or otherwise controlled environments whenever possible. Apply appropriate isolation, access controls, rate limits, logging, monitoring, privacy protections, and evidence-handling procedures. Use synthetic or redacted data where appropriate.
Do not probe third-party systems, extract real secrets, bypass safeguards outside the approved scope, or use harmful payloads. If a critical condition appears, the team needs a clear path to notify the owner and pause testing.
2. Inventory the AI attack surface and threat-model the deployment
Create the system map before choosing tests. Record components, trust boundaries, data flows, privileges, external dependencies, deployment versions, and changes that could alter risk.
| Component | What to document |
|---|---|
| Models | Model versions, providers, deployment locations, interfaces, and fallback behavior |
| Applications and prompts | User journeys, system prompts, templates, orchestration logic, output handling, and access controls |
| Data and retrieval | Data sources, sensitivity, permissions, ingestion paths, RAG components, retrieval rules, and vector stores |
| Tools and APIs | Available functions, credentials, scopes, input validation, external services, and audit trails |
| Agents and memory | Planning, state, memory, handoffs, autonomy, approval steps, and action limits |
| Downstream integrations | Business systems, user accounts, databases, queues, workflows, and consequences of incorrect output |
Turn the inventory into a deployment-specific threat model. Identify protected assets, relevant adversaries, intended use, attack surfaces, data boundaries, privileges, and failure modes. Include leakage, unsafe content, unreliable output, unauthorized access, harmful actions, and integration failures. For a broader treatment of this process, see AI threat modeling guide.
Map coverage to established guidance
Use frameworks to organize coverage rather than treating any one framework as mandatory. Map applicable risks and test categories to the OWASP GenAI and LLM guidance, MITRE ATLAS, and the NIST AI Risk Management Framework. Record applicable risks, corresponding tests, and remaining coverage gaps.
3. Build the multidisciplinary team and operating model
AI red teaming spans technical behavior, application security, safety, business context, and governance. Assemble the capabilities required by the deployment rather than assuming a fixed team structure.
- Security: application, API, identity, infrastructure, and access-control risks
- Machine learning and software engineering: model behavior, pipelines, code, prompts, and integrations
- Product and domain expertise: intended workflows, business consequences, and realistic misuse
- Safety, responsible AI, behavioral, and privacy expertise: harmful, biased, sensitive, or unreliable outcomes
- Legal, compliance, risk, and communications: authorization, disclosure, escalation, and governance needs
Define intake, approvals, evidence handling, finding ownership, remediation tracking, escalation, and retest sign-off. Staffing levels, budgets, and ratios are deployment-specific decisions, not universal requirements.
4. Choose manual, automated, or hybrid testing
| Approach | Strengths | Limitations and appropriate use |
|---|---|---|
| Manual expert probing | Creative, contextual, and useful for unusual workflows and business consequences | Slower and harder to reproduce at scale; use for high-risk paths and expert analysis |
| Automated evaluation | Scalable, repeatable, and useful for regression testing and broad coverage | Can miss context or produce misleading results; require expert review |
| Hybrid testing | Combines expert judgment with automation, repeatability, and scale | Requires integration and result-triage discipline; use as the operating default as the program matures |
Combine manual expert probing with automated evaluation or red-teaming frameworks. Evaluate tools and platforms against coverage, repeatability, integration, data handling, and reporting. Examples such as Promptfoo or PyRIT are options, not requirements, and no single platform is universally best.
Automated results require human review before mitigation or risk-acceptance decisions, especially when outputs are nondeterministic or severity depends on business context.
5. Create a risk-based test plan
Translate the threat model into prioritized scenarios and a reusable test library. Start with workflows where failure would have the greatest business or safety consequences. For each scenario, define expected behavior, the test condition, evidence to capture, and the pass-or-fail interpretation. For a broader risk-assessment workflow, see AI security risk assessment.
Cover the major risk categories
- Model and safety: jailbreak resistance, harmful content, bias, unsafe recommendations, and reliability failures
- Security and privacy: prompt injection, data leakage, unauthorized access, credential exposure, and privilege abuse
- Data: poisoning, unauthorized retrieval, boundary violations, manipulated context, and unsafe ingestion
- Application: weak access controls, insecure APIs, unsafe output handling, and integration failures
- Misuse: workflows that enable harmful or unauthorized use of the system
Keep scenarios defensive and controlled. The plan should show what is being assessed and how impact will be demonstrated without providing operational instructions for attacking third-party systems or extracting real secrets.
6. Test RAG, agents, tools, APIs, and integrations
A modern AI red teaming program extends beyond the base model. Test how untrusted inputs and retrieved content move through the application, and what actions the system can take.
Assess retrieval and data stores
Evaluate retrieval permissions, tenant and data boundaries, ingestion controls, source trust, vector-store isolation, and how retrieved content influences responses. Include indirect prompt-injection scenarios in which untrusted content attempts to influence system behavior.
Assess agents and tools
Check whether an agent can use tools outside its intended authority, manipulate memory or data, abuse privileges, take excessive action, or fail during orchestration. Review approval gates, identity propagation, tool permissions, action validation, and audit records. For a focused treatment of these identity and permission risks, see AI agent privilege abuse.
Relevant categories include unauthorized tool use, indirect prompt injection, memory or data manipulation, privilege abuse, excessive agency, and orchestration failures. Separate model-level findings from application- and system-level findings because severity often depends on the access and authority provided by the surrounding application.
7. Execute assessments and evaluate real-world impact
Run every campaign as a repeatable workflow:
- Establish a baseline using expected use cases and known-safe behavior.
- Run prioritized manual, automated, or hybrid scenarios against the approved environment.
- Capture relevant inputs, outputs, configuration, model version, retrieved context, tool calls, and system response.
- Repeat important scenarios to account for nondeterministic behavior.
- Have an expert review automated results and remove false positives.
- Demonstrate the business or safety consequence without expanding beyond the authorization.
Prioritize findings by real-world business and safety impact, not by the cleverness of a jailbreak or the novelty of a payload. Consider affected assets, likelihood, required access, exposure, potential harm, reversibility, and whether the system can take consequential action.
Track useful program metrics
- Attack Success Rate: successful attacks divided by total attacks
- Coverage across applications, workflows, components, and risk categories
- Finding severity and the distribution of security, safety, privacy, and reliability issues
- Remediation time and, where appropriate, Mean Time to Compromise
- False-positive rate and the share of automated results requiring analyst correction
- Regression results after model, prompt, data, tool, or integration changes
Use metrics to expose blind spots and improve decisions. Targets are illustrative, not universal benchmarks. For guidance on measuring program performance, see AI security metrics and KPIs.
8. Report reproducible findings
Every finding should connect evidence to an affected component and an actionable decision. A practical report includes:
- Finding title, risk category, severity, and affected workflow
- Component and environment, including the relevant model or configuration version
- Reproduction conditions and attack details within the authorized boundary
- Inputs, outputs, logs, tool calls, retrieved context, and supporting evidence
- Business, safety, privacy, security, or reliability impact
- Recommended remediation and compensating controls
- Assigned owner, workflow, escalation, and risk-acceptance decision
- Retest status, residual risk, and closure evidence
Evidence should allow another authorized team member to understand and reproduce the result. Do not treat a single surprising output as a confirmed vulnerability without checking the conditions and affected component.
9. Remediate and validate the fix
Assign each finding to the team that can change the affected component. A fix may involve model or prompt changes, access controls, retrieval filtering, data correction, tool-permission changes, orchestration safeguards, monitoring, or a change to the surrounding application.
Retest the original scenario and related cases after remediation. Confirm that the mitigation addresses the affected component rather than simply hiding the observed output, and check that it does not create a new failure elsewhere. Record the retest result, residual risk, and any formally accepted risk.
10. Integrate continuous testing and scale program maturity
Regression testing belongs in release and change management. Add relevant test suites to CI/CD where the environment and data controls support it, and use scheduled lifecycle checkpoints for broader assessments.
Trigger targeted retesting after:
- Model or model-version changes
- System-prompt, orchestration, or application changes
- Retrieval-data, indexing, or vector-store changes
- New tools, APIs, permissions, agents, or memory behavior
- Changes to downstream integrations or important business workflows
Keep a regression corpus of authorized scenarios and track which risks each test covers. Continuous testing preserves known coverage between deeper expert campaigns; it does not replace them.
Progress from pilot to governance
- Scoped pilot: one application, defined workflows, written authorization, inventory, threat model, and initial findings.
- Repeatable campaigns: reusable test plans, reporting templates, ownership, remediation tracking, and scheduled reassessment.
- Automated regression: hybrid evaluation connected to release or change-management workflows, with expert review.
- Organizational governance: broader application coverage, common risk reporting, escalation, risk acceptance, and lifecycle checkpoints.
Review staffing, training, tools, and budget as the pilot reveals workload and risk. Do not assume that a fixed team size, platform, or assessment cadence fits every deployment.
AI red teaming program checklist
- Written objectives, scope, ownership, authorization, safety boundaries, and rules of engagement
- Inventory of models, prompts, applications, data, RAG, vector stores, APIs, tools, agents, and integrations
- Deployment-specific threat model mapped to OWASP GenAI/LLM guidance, MITRE ATLAS, and NIST AI RMF
- Security, ML, software, product, domain, safety, legal, and compliance capabilities as required
- Risk-based test plan combining manual expertise with automated repeatability
- Coverage for model, application, data, privacy, safety, reliability, RAG, agent, tool, API, and misuse risks
- Reproducible, impact-based findings with owners, remediation, and retest status
- Change-triggered regression testing after model, prompt, retrieval, tool, or integration changes
The goal is not a one-time declaration that an AI system is safe. Build a controlled pilot, learn from its findings, automate repeatable checks, and make AI red teaming part of the system’s ongoing development and governance lifecycle.