
Key takeaways
- Model inversion attacks are privacy attacks in which an adversary exploits a trained machine-learning model—using its outputs and, in stronger cases, internal parameters or gradients—to infer sensitive attributes or reconstruct information about training examples. They are more feasible when the model memorizes or overfits its training data. Key defenses are differential privacy, limiting output granularity, restricting and monitoring queries, and reducing memorization.
- Apply differential privacy or other privacy-preserving training methods.
- Reduce confidence-score or prediction-detail exposure.
- Restrict authentication, query volume, and bulk probing.
- Monitor for anomalous repeated queries and test models for memorization or inversion risk.
Model inversion attacks are privacy attacks in which an adversary exploits a trained machine-learning model—using its outputs and, in stronger cases, internal parameters or gradients—to infer sensitive attributes or reconstruct information about training examples. They are more feasible when the model memorizes or overfits its training data.
Key defenses include differential privacy, less detailed outputs, strong access controls, query limits and monitoring, sensitive-data minimization, and reducing memorization. The target is information encoded in or processed by the model—not primarily its architecture or functionality.
What Is a Model Inversion Attack?
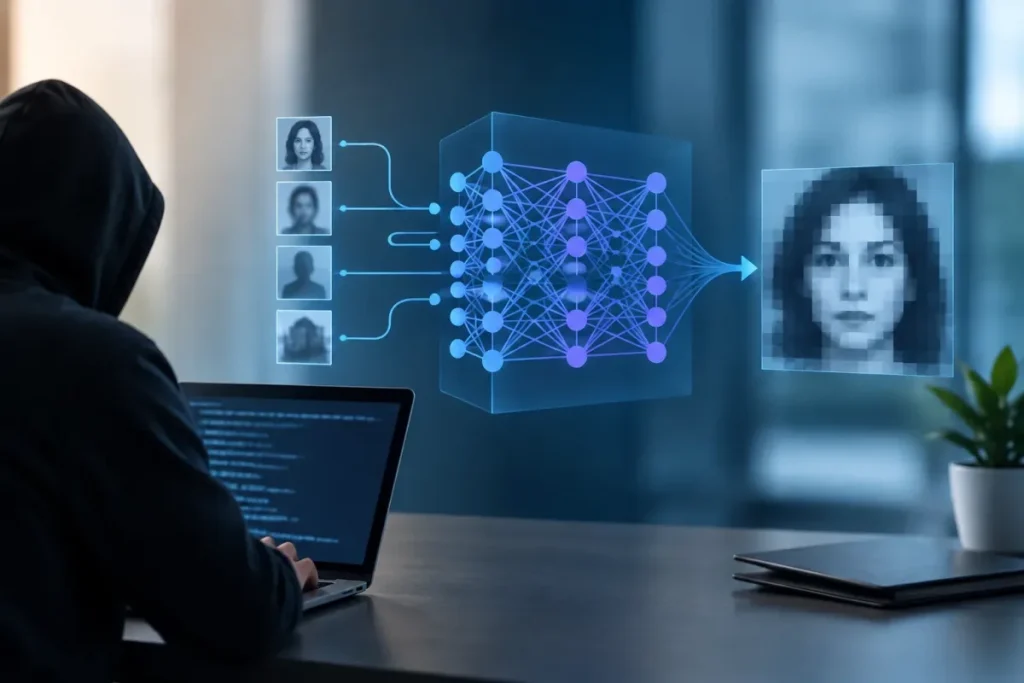
A model inversion attack uses access to a machine-learning system to infer sensitive characteristics or reconstruct information associated with training data or processed inputs. The attacker analyzes what the model reveals and works backward toward information the model has learned.
Access may be limited to a prediction API or may include internal model information. A result could be an inferred medical attribute, a recognizable facial feature, or an approximate representation of a training example. It does not necessarily reveal an exact record, and inversion is not the same as directly accessing a database.
How Model Inversion Attacks Work
The process varies by system and access level, but the high-level pattern is:
- Access the model: The attacker interacts with a deployed service or obtains internal information, depending on the threat model.
- Observe available signals: These may include labels, probabilities, confidence scores, generated responses, representations, parameters, or gradients.
- Analyze the signals: The attacker looks for patterns associated with sensitive features, training examples, or processed inputs.
- Infer or reconstruct information: The result may be a sensitive attribute or an approximate, representative, or recognizable example.
Method categories include feature or gradient optimization, surrogate models, generative priors, pixel-space searches, and repeated label-only observations. These approaches are not guarantees of success. Auxiliary knowledge may improve an inference, while a poor match between the attacker’s assumptions and the private data may reduce reconstruction quality.
Success depends on model behavior, training data, memorization, attacker knowledge, available access, query limits, and deployment conditions. A model that generalizes well may reveal less than one that has memorized specific examples.
Black-Box Versus White-Box Inversion
Black-box access
Black-box model inversion relies on queries and observable outputs without direct access to the model’s internal construction. Depending on the interface, the attacker may see only hard labels or may also receive probabilities, confidence scores, or generated responses. For a broader comparison of these testing perspectives, see black-box and white-box AI penetration testing.
Black-box access is not unlimited access. Authentication, rate limits, query budgets, logging, and output restrictions can reduce the information available. An interface that exposes highly detailed responses can create greater privacy risk.
White-box access
White-box model inversion involves internal information such as architecture, parameters, representations, or gradients. These signals can provide information that an ordinary prediction API does not expose, but they do not automatically produce a complete or precise reconstruction.
White-box access is a stronger capability, not a universal requirement. Both black-box and white-box outcomes depend on what the model retained and how much useful information the attacker can observe.
| Aspect | Black-box inversion | White-box inversion |
|---|---|---|
| Access | Queries to a model interface and returned outputs | Internal model information in addition to, or instead of, ordinary outputs |
| Signals | Labels, probabilities, confidence scores, or completions | Parameters, representations, architecture, gradients, and outputs |
| Possible outcome | Inferred attributes or approximate, recognizable information | Inferences or reconstructions supported by additional internal signals |
What Can Model Inversion Expose?
Training-data inversion attempts to reconstruct information resembling examples used to train the model. Input-feature inversion instead seeks characteristics of a particular input that the model has processed. These targets can overlap, but they are not identical.
- Recognizable faces or other visual features
- Medical or genetic information
- Personally identifiable information
- Confidential documents
- Proprietary or copyrighted material
- Behavioral characteristics
- Relationships represented in a graph
Not every model inversion attack can expose every category. Potential exposure depends on the training data, learned representations, interface, and protections.
Examples
A medical classification model that returns a prediction and confidence value may reveal a sensitive medical or genetic characteristic if it has retained unusually specific patterns. That would be an inference about sensitive information—not proof that the attacker recovered the person’s complete medical record.
Similarly, an image model that has memorized unusually specific features from training examples might support a recognizable reconstruction. The result could resemble an important feature without being the original image or a verbatim training record.
Exact record recovery is not guaranteed. Results may be approximate, representative, or recognizable. Fidelity depends on memorization, overfitting, attacker knowledge, query limits, available signals, and how well reconstruction assumptions match the private data.
Model Inversion Compared With Related Attacks
| Attack | Objective | Primary target | Typical outcome |
|---|---|---|---|
| Model inversion | Infer sensitive attributes or reconstruct information | Training data or information processed by the model | An inferred characteristic or approximate, representative, or recognizable reconstruction |
| Model extraction or model stealing | Replicate the model’s functionality or behavior | The model itself | A substitute model that imitates predictions or functionality |
| Membership inference | Determine whether a particular record appeared in training | Training-set membership | An indication that a specific record was or was not included |
| Gradient inversion | Reconstruct inputs from shared gradients | Inputs represented by gradients | An inference or reconstruction of the original input |
The distinction matters. Model extraction targets functionality, whereas inversion targets sensitive information. Membership inference asks whether a record was included; it does not, by itself, seek to reconstruct the record’s contents. Gradient inversion focuses specifically on information recoverable from shared gradient signals.
Which Systems May Be Affected?
Model inversion is not limited to large language models. It can concern image, text, language, multimodal, and graph systems, including facial-recognition, medical, recommendation, and API-deployed models.
- Image and facial systems: Recognizable faces or visual features may be exposed.
- Text and language models: Outputs or completions may reveal information reflected in learned text patterns.
- Multimodal systems: Multiple input types may create different learned signals and exposure paths.
- Graph systems: Relationships or structural information may be sensitive.
- Medical and recommendation systems: Health, genetic, behavioral, or preference information may be involved.
These systems do not face identical risks. Feasibility and potential exposure depend on the model, data, interface, attacker access, and surrounding controls.
Risks and Practical Limitations
The central risk is unauthorized disclosure of sensitive information. Depending on the data involved, inversion may expose confidential, proprietary, copyrighted, behavioral, biometric, or personally identifying information.
- Memorization and overfitting: Risk increases when a model retains specific training instances instead of learning generalized patterns.
- Access level: Detailed outputs or internal signals can provide more information than a restricted label-only interface.
- Attacker knowledge: Relevant prior information can make an inference more useful.
- Query budget: Rate limits and restricted access reduce the observations available for analysis.
- Prior mismatch: Reconstruction assumptions may fit poorly when they do not match the private data.
- Deployment conditions: The API, monitoring, model updates, and surrounding safeguards affect exposure.
Teams can assess risk using reconstruction fidelity, attack success, privacy leakage, distributional similarity, utility, computation, and query cost. These measures should be considered together: a recognizable result may matter even when it is not an exact record. For ways to organize and report these measures, see AI security metrics and KPIs.
How to Defend Against Model Inversion Attacks
1. Protect training data and reduce memorization
- Apply differential privacy or other privacy-preserving training methods where appropriate to reduce the connection between model behavior and individual training examples.
- Minimize sensitive training data. Avoid collecting or retaining information the model does not need.
- Reduce overfitting and memorization. Assess whether the model retains specific examples unnecessarily and improve generalization where possible.
- Use suitable design controls, such as representation regularization or feature masking, when they fit the system’s purpose.
2. Limit exposed outputs and access
- Reduce the precision or granularity of confidence scores and probability outputs when users do not need that detail.
- Return only the information required for the use case rather than unnecessary representations or metadata.
- Require authentication and apply appropriate access controls to model interfaces.
- Enforce rate limits and query budgets, especially for sensitive models and bulk-access APIs.
3. Monitor and test for privacy leakage
- Log model access and review repeated, adaptive, or unusually frequent queries.
- Monitor for unusual input variation or output patterns that may indicate systematic probing.
- Perform defensive testing for memorization, model inversion, membership inference, and related privacy risks.
- Reassess the model when its training data, interface, outputs, or deployment conditions change.
These controls involve trade-offs. Differential privacy and stronger data protections can affect model utility; output coarsening can reduce user-visible detail; access restrictions can add friction; and monitoring requires operational resources. The appropriate balance depends on data sensitivity and the model’s purpose. For a practical framework for ongoing observation, see AI security monitoring.
No single defense completely eliminates model inversion risk. Layered protection is more reliable: protect the data, reduce memorization, limit output detail, secure the API, monitor behavior, and test the deployed system. For a testing checklist focused on deployed model APIs, see AI API penetration testing.
Practical Defensive Checklist
- Review training data for sensitive, confidential, proprietary, identifying, or copyrighted information.
- Assess overfitting and memorization before and after deployment.
- Expose only the prediction, probability, or confidence detail users actually need.
- Apply authentication, access controls, rate limits, and query budgets.
- Log and monitor repeated, adaptive, unusually frequent, or varied queries.
- Test for inversion and related privacy risks under realistic access conditions.
- Reevaluate protections when the model, data, interface, or deployment changes.
Conclusion
Model inversion attacks use model behavior—or, with stronger access, internal parameters and gradients—to infer sensitive attributes or reconstruct information from training data or processed inputs. They target information learned by the model, not primarily its functionality.
Feasibility depends on memorization, overfitting, access, attacker knowledge, query limits, available signals, and deployment conditions. Differential privacy, sensitive-data minimization, reduced memorization, less detailed outputs, access controls, rate limits, logging, monitoring, and defensive testing provide a layered way to reduce the risk.