
Key takeaways
- Model extraction attacks—also called model stealing—use systematic queries or other observable model behavior to build a functionally similar surrogate of a proprietary AI system, typically without access to its source code or internal weights. The primary defenses are limiting and monitoring queries and reducing the information exposed by model outputs.
- Apply rate limits, quotas, and authentication controls.
- Monitor for automated, systematic, or anomalous query behavior.
- Limit high-information outputs such as confidence scores, probabilities, or unrestricted log probabilities where appropriate.
- Use output perturbation or other information-reduction techniques, balancing utility and robustness.
Model extraction attacks—also called model stealing—use systematic queries or other observable behavior to build a functionally similar surrogate of a proprietary AI system without access to its source code or internal weights. Primary defenses limit and monitor queries and reduce exposed output information.
- Model extraction targets a system’s behavior and capabilities, not necessarily its exact weights, architecture, or training data.
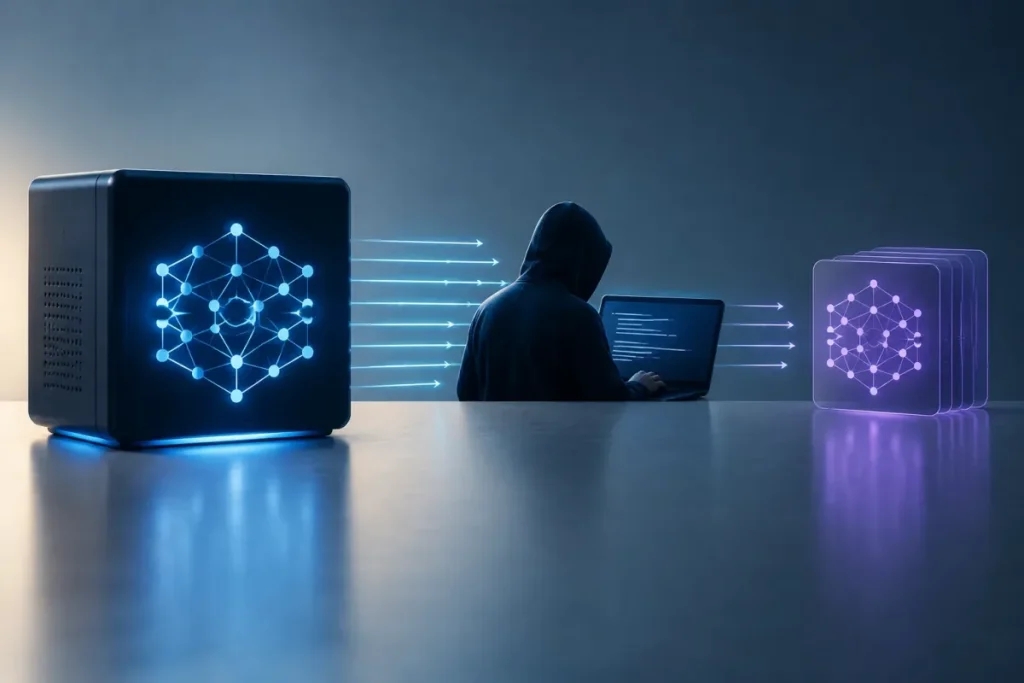
- In the usual black-box workflow, an attacker collects input-output pairs from a deployed model and uses them to train a surrogate model.
- Main risks include intellectual-property loss, unauthorized capability replication, loss of control over safety restrictions, and offline security testing.
- Layered defenses include authentication, rate limits, query monitoring, reduced output detail, output perturbation, watermarking, and privacy-preserving practices where relevant.
What are model extraction attacks?
A model extraction attack targets a deployed or public-facing AI system, such as a classifier, recommender, language model, or API-based service. The attacker attempts to reproduce useful decisions, rankings, predictions, or capabilities in a separate surrogate model.
This is an attack against the model’s behavior and proprietary capabilities—not merely general reverse engineering. The objective is functional replication. A substitute can be useful even when it does not match the original implementation internally. Exact parameter or architecture recovery is a specialized possibility, not a requirement.
Not every API query or replication attempt is a successful extraction attack. The defining pattern is the systematic use of observable behavior to create a substitute that approximates the target.
How the black-box workflow works
In a black-box model extraction scenario, the requester cannot directly inspect the target’s source code or internal weights. Instead, the deployed model returns information in response to inputs. Those responses reveal aspects of how the target classifies, ranks, predicts, or generates content.
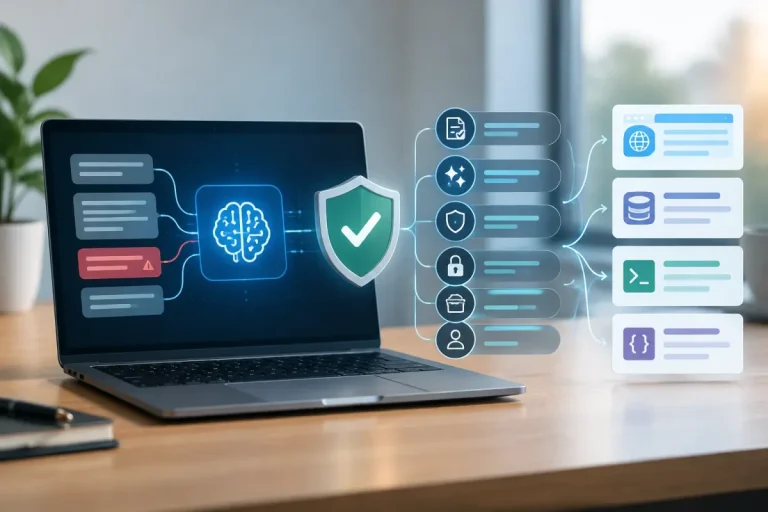
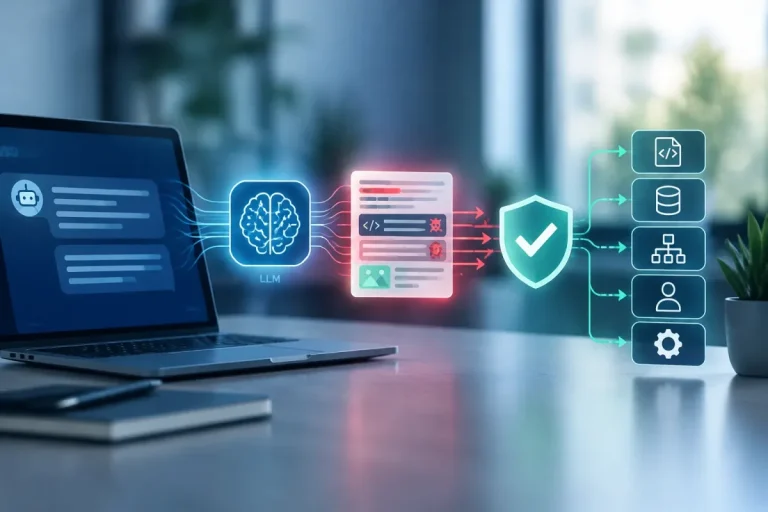
At a high level, the workflow has three parts:
- Query the target: submit a systematic collection of inputs to the deployed service.
- Collect observable outputs: record the labels, scores, probabilities, or generated responses that the service exposes.
- Train a substitute: use the input-output pairs as learning material for a local student or surrogate model.
Query selection can range from broad sampling to more informative approaches, including systematic variation or active learning. These choices affect the information gained per request, access costs, and detection risk.
What information can model outputs reveal?
The detail of an API response affects how much information it exposes about the target’s behavior. Common output types include:
- Hard labels: the selected class, decision, or outcome.
- Confidence scores: indications of how strongly the model favors an outcome.
- Probabilities: a distribution across possible classes or responses.
- Logits and log probabilities: more granular information about relative model preferences, when exposed.
- Generated text: examples of a language model’s response patterns and capabilities.
Richer outputs can support a closer behavioral approximation than a final label alone. Probability-related information can reveal more about the target’s decision behavior or output preferences, although no single output format guarantees successful extraction.
For language models, token-level probabilities or log probabilities can expose additional behavioral detail. Output design is therefore an important security decision: providers must balance useful transparency and product functionality against unnecessary information leakage.
Model extraction versus related attacks
Several AI security terms are sometimes grouped together, especially in discussions of language models. Their primary objectives differ:
| Attack type | Primary objective | Typical outcome sought |
|---|---|---|
| Model extraction or model stealing | Replicate model functionality or capabilities | A functionally similar surrogate model |
| Training-data extraction | Obtain information from data used to train the model | Exposed or recovered training-set content |
| Model inversion | Reconstruct sensitive information from model behavior | Inferred information about data or subjects |
| Membership inference | Determine whether a particular sample was used for training | An inference about training-set membership |
Model extraction primarily targets behavior. It does not necessarily recover training data, confidential prompts, memorized information, exact parameters, or the complete original model. Training-data extraction, model inversion, and membership inference primarily concern information about data or its use, although these threats can overlap in practice.
Risks and attacker motivations
Model extraction attacks against AI systems create both business and security risks:
- Intellectual-property loss: proprietary capabilities can be replicated without repeating the original development investment.
- Unauthorized capability replication: a substitute may reproduce valuable classification, ranking, prediction, or conversational behavior.
- Reduced API dependence: a local surrogate can reduce reliance on continued access to the original service and its usage costs.
- Loss of control over safety restrictions: an independently operated substitute may not preserve the original service’s controls.
- Offline security analysis: a substitute gives an attacker a local environment for testing potential weaknesses without repeatedly interacting with production.
The impact depends on the surrogate’s fidelity and usefulness. Extraction does not necessarily remove the original system’s safety restrictions, reveal confidential prompts, recover memorized data, or reproduce every capability; it creates a separate system that may approximate important behavior.
Detection and monitoring
Providers can look for behavior consistent with systematic extraction rather than relying on a single alert threshold. Relevant signals include:. For broader guidance on monitoring AI systems, see AI security monitoring.
- Unusual query volume, timing, or continuity
- Highly systematic variation in inputs
- Input distributions that differ from ordinary product use
- Repeated or coordinated activity across accounts
- Unusual IP behavior or access patterns
- Repeated requests for unusually informative outputs
Structured traffic is not automatically malicious: legitimate testing, research, and high-volume applications can also produce regular request patterns. Effective monitoring therefore combines multiple signals with account, application, and usage context.
Watermarking and behavioral fingerprints can help establish provenance or identify a suspected substitute. Verification queries can test whether a candidate model reproduces distinctive behaviors associated with the target. These are attribution and detection mechanisms, not guaranteed proof or universal prevention.
Defense-in-depth controls
Restrict access and query volume
Providers can reduce extraction feasibility by controlling who can access a model and how much information each identity can obtain. Core controls include:
- Authentication and authorization
- Account- and application-level access controls
- Rate limits and quotas
- Query budgets and usage limits
- Monitoring for automated, systematic, or anomalous behavior
These controls limit the volume and continuity of observations available to a potential extractor. They reduce risk but do not make extraction universally impossible.
Reduce information exposed by outputs
Where product requirements allow, a service can return less detailed information. Possible measures include:. For practical guidance on validating and sanitizing generated content, see LLM output security.
- Returning hard labels instead of full probability distributions
- Rounding or coarsening scores
- Restricting logits and unrestricted log-probability exposure
- Truncating responses where appropriate
- Applying carefully designed noise or output perturbation
Less detailed output can make high-fidelity approximation more difficult, but it can also affect legitimate users. Noise, perturbation, and aggressive truncation must be evaluated against service utility and robustness. No single output control is universally foolproof.
Use attribution, privacy, and architectural controls
Watermarking, behavioral fingerprinting, and verification queries can support attribution after suspected replication. Keeping proprietary capabilities behind a business-logic layer rather than exposing the core model directly can also reduce direct model exposure.
When sensitive data leakage is part of the threat, privacy-preserving training and deployment practices are relevant. Differential privacy is one privacy-oriented control that can reduce data exposure, but it is not a complete solution to every model-extraction scenario.
LLM-specific considerations
Common model-extraction categories include functionality extraction, API-based distillation, parameter recovery, and prompt-targeted extraction. These describe different research directions, not requirements of every attack.
For a language model, functionality extraction may target conversational capabilities or other observable behavior. Parameter recovery focuses on internal model structure, while prompt-targeted research focuses on prompts or instructions. None of these categories changes the central definition: ordinary model stealing seeks a useful behavioral substitute and does not necessarily recover training data, system instructions, or exact internal parameters.
How should extraction defenses be evaluated?
A meaningful evaluation should examine more than whether a surrogate exists. Relevant dimensions include:
- Surrogate fidelity: how closely the substitute reproduces the target’s decisions, rankings, accuracy, or capabilities.
- Query efficiency: how much useful behavioral information is obtained from available observations.
- Cost and operational burden: the resources and access required to produce a useful substitute.
- Detection quality: how well monitoring identifies systematic extraction while distinguishing legitimate use.
- Defense performance: how much a control reduces information leakage or surrogate fidelity.
- Service utility: how access restrictions, output reduction, or perturbation affect legitimate users.
These dimensions can conflict. A defense that reduces output information may also reduce product usefulness, while a more permissive API may improve usability but expose more behavior. No single method or defense is universally best; effectiveness depends on the balance among security, utility, cost, and detection.
Conclusion
Model extraction attacks against AI systems target behavior rather than necessarily recovering a model’s internals. The ordinary black-box pattern is systematic querying, collection of observable outputs, and surrogate-model training. The main consequences include intellectual-property loss, unauthorized replication, weakened control over safety restrictions, and potential offline security testing.
Effective risk reduction combines authentication, rate limits, quotas, query monitoring, reduced output detail, attribution mechanisms, and privacy-preserving practices where appropriate. These controls reduce extraction feasibility and information leakage, but none should be treated as universally foolproof.