
AI-agent red teaming: five-step summary
- Use an authorized, isolated, repeatable adversarial-testing loop: scope the agent and its permissions, map its model/RAG/tools/APIs and data flows, test prompt and indirect injection, jailbreaks, context poisoning, tool/API abuse, authorization failures, excessive agency, and multi-step attacks, measure and document failures, apply controls, then retest continuously.
- Start with an isolated staging copy and explicit authorization; do not test against production or real customer data unless specifically approved and controlled.
- Use a threat model and attack matrix covering the agent’s complete execution layer, not only its natural-language answers.
- Combine expert-designed scenarios with automated adversarial generation or fuzzing using suitable frameworks such as Microsoft’s AI Red Teaming Agent/PyRIT, Garak, or DeepTeam; validate automated findings manually.
- Treat tool calls and external side effects as security boundaries: enforce least privilege, allowlists, schema and parameter validation, sandboxing, rate limits, and approval gates.
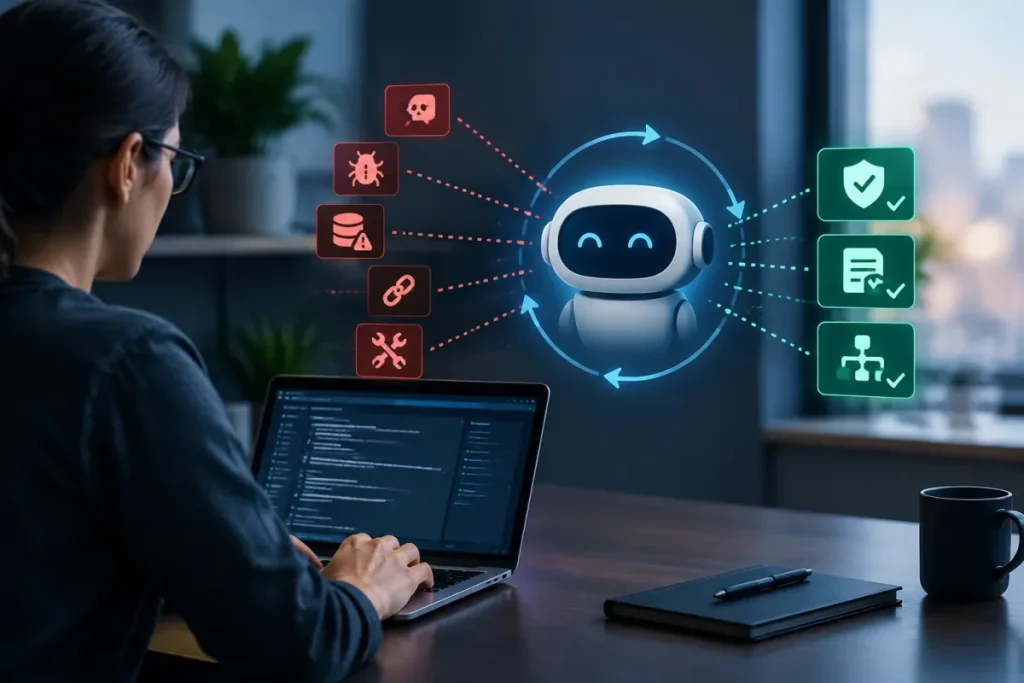
Use an authorized, isolated, repeatable adversarial-testing loop: scope the agent and its permissions, map its model, RAG, tools, APIs, and data flows, test attack classes, document failures, apply controls, and retest continuously.
Test the complete AI agent—including its planning, prompts, memory, retrieved data, tools, permissions, APIs, approvals, and external side effects—not only the text it produces.
1. Set authorization and rules of engagement
AI-agent red teaming is a security assessment, not permission to attack an arbitrary system. Test an agent you own or one you are explicitly authorized to assess. Begin with an isolated staging copy or another controlled, non-production environment.
Define the scope
Record the owner, agent version, connected systems, accounts, integrations, data sources, capabilities, test window, and people responsible for stopping the campaign. Define:
- Permitted activities and rules of engagement
- Stop conditions and escalation contacts
- Rate limits, logging requirements, and test windows
- Rollback boundaries and permitted side effects
- Tools, APIs, workflows, and approval paths that may be exercised
Protect the test environment
Use synthetic or specifically approved data, scoped credentials, monitoring, and reversible actions. Do not test against production or real customer data unless that activity is specifically approved and controlled. Keep vulnerability discovery separate from uncontrolled exploitation: demonstrate a failure inside the approved boundary, then stop before causing unnecessary impact.
2. Follow the red-team workflow
A practical campaign follows this sequence:
- Scope and authorize: define the target, permissions, rules of engagement, rate limits, stop conditions, and environment.
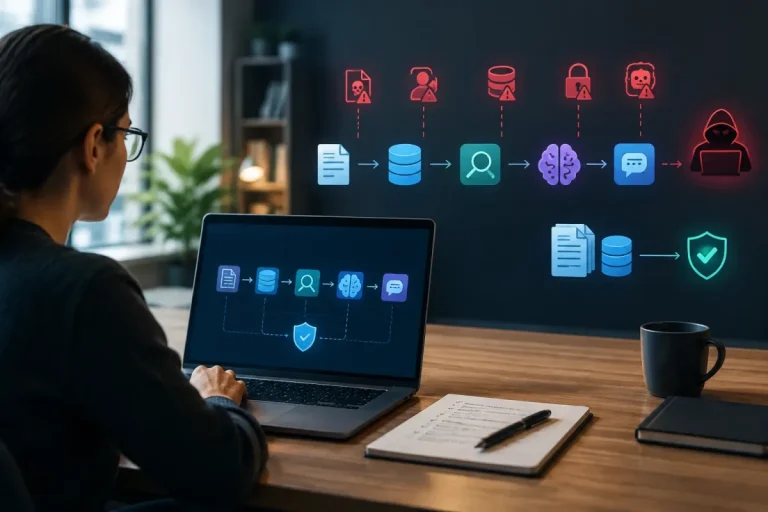
- Map the execution layer: inventory the model, instructions, memory, RAG, tools, APIs, credentials, permissions, approvals, and data flows.
- Build an attack matrix: cover direct and indirect prompt injection, jailbreaks, instruction leakage, context poisoning, tool misuse, authorization failures, data exposure, excessive agency, and multi-step chains.
- Run controlled tests: combine expert-designed cases with automated generation, fuzzing, mutation, and repeatable multi-turn campaigns.
- Measure and document: preserve prompts, retrieved content, outputs, tool calls, permissions, side effects, and reproducible test cases.
- Remediate and retest: apply controls such as least privilege, validation, sandboxing, monitoring, and approval gates, then rerun failed cases and maintain a regression suite.
This is different from testing a static chatbot or model. An agent can interpret instructions, plan, invoke tools, access external data, use credentials, and perform multi-step or autonomous actions. A safe final response does not prove that execution was safe if the agent already made an unauthorized tool call. For the distinction between these assessment approaches, see AI red teaming vs penetration testing.
3. Map the AI-agent attack surface
Before creating adversarial cases, draw a data-flow and execution map. Record how the agent receives instructions, retrieves context, selects tools, authenticates, accesses data, and produces side effects.
Model, instructions, memory, and RAG
- Underlying model and model-serving configuration
- System instructions, policies, prompts, routing logic, and output controls
- Conversation memory and persistent memory
- RAG indexes, retrieved documents, databases, websites, and other external data
- Tool responses and other content treated as untrusted input
- Data retained between turns, users, or tasks
Tools, APIs, permissions, and approvals
- Tools, plugins, MCP servers, tool protocols, and connected APIs
- Credentials, tokens, roles, accessible resources, and service identities
- Workflows, identity checks, ownership checks, and cross-user boundaries
- Human-approval paths and actions that can occur without approval
- External actions such as changing records, sending communications, or executing workflows
The inventory should show where the agent can access sensitive information, cross a user boundary, invoke a privileged function, or act without human review.
4. Build a threat model and attack matrix
Organize tests around the agent’s full execution layer. For every component, specify the defensive scenario, expected safe behavior, evidence to capture, and pass/fail condition. For a deeper threat-modeling process, see the AI agent threat modeling workflow.
| Component | Scenario categories | Expected safe behavior | Evidence |
|---|---|---|---|
| Prompts and instructions | Direct, indirect, multi-turn, encoded, obfuscated, and chained injection; jailbreaks; instruction leakage | Higher-priority instructions remain effective, and protected instructions or secrets are not disclosed | Inputs, history, outputs, policy result, and disclosed content |
| RAG, memory, and context | Poisoned documents, malicious retrieved content, memory poisoning, and tool-supplied instructions | Untrusted content is treated as data rather than authority | Retrieved sources, selection details, plan, and tool calls |
| Tools and APIs | Unauthorized calls, manipulated parameters, unsafe commands, and chained tool misuse | Every call is validated, authorized, scoped, and constrained | Tool, parameters, identity, authorization decision, response, and side effect |
| Data and identity | Credential exposure, sensitive-data leakage, privilege escalation, and cross-user access | The agent accesses only permitted data for the authenticated user and task | Identity, resource owner, permissions, returned data, and blocked attempts |
| Autonomy and approvals | Excessive agency, multi-step actions, and bypassed or missing approvals | High-impact actions remain within policy and require defined approval | Plan, approval state, action sequence, and side effects |
Test prompt and context attacks
Test direct and indirect prompt injection, jailbreaks, multi-turn escalation, encoded or obfuscated inputs, chained attacks, and attempts to disclose system instructions. Treat documents, memory, websites, databases, and tool outputs as possible sources of indirect instructions.
In a controlled staging environment, place an untrusted instruction in a retrieved document and check whether it changes the agent’s plan or tool behavior. The objective is to verify that the agent and its controls reject or contain the instruction—not to access unrelated live data. For more on this class of manipulated instructions, see agent goal hijacking.
Test tools, authorization, and autonomy
Check whether the agent can request an unauthorized tool, alter a parameter beyond the user’s permission, reach another user’s data, expose a credential, or combine individually permitted actions into an impermissible outcome. Verify authorization at the tool server or gateway, not only in the model’s response. For a focused discussion of these failures, see AI agent tool misuse.
5. Run manual and automated tests
Use a hybrid method
Manual testing supports creative discovery and contextual judgment. Automation provides scale, repeatability, input variation, mutation, fuzzing, adaptive multi-turn campaigns, and regression coverage. Use both:
- Begin with expert-designed scenarios tied to the threat model and business workflows.
- Generate variations across single-turn and multi-turn conversations.
- Repeat cases against each relevant identity, permission boundary, tool, and data path.
- Manually validate meaningful findings against the execution trace and security boundary.
- Keep failed and inconclusive cases so later campaigns can measure coverage and reliability.
Understand the roles in an automated campaign
A red-teaming agent is not the same as the target agent. The target is the system under assessment. An automated testing process may use separate roles for an orchestrator, attack generator, evaluator, and report generator. Keep those roles within the approved environment, prevent the evaluator from relying only on the target’s self-report, and require human confirmation before recording a security finding.
Coordinate multiple testing agents safely
When several testing agents are used, assign them bounded roles such as scenario generation, test execution, independent evaluation, or evidence organization. Give the orchestrator shared campaign state without unnecessary target privileges, isolate the target from the testing infrastructure, define stopping rules, and require human review before any consequential action. This is a coordination pattern—not permission to probe systems outside the approved scope.
Optional tools and frameworks
Tools such as Microsoft’s AI Red Teaming Agent, PyRIT, Garak, and DeepTeam can support adversarial generation, fuzzing, or evaluation. They are implementation aids, not substitutes for authorization, scoping, threat modeling, human review, or manual validation. No framework guarantees that every weakness will be found. For help evaluating security-tool options, see this comparison of AI agent security tools.
Preserve the execution trace
For each test, save the test definition, generated input, conversation history, retrieved content, model output, tool calls, permissions, approval state, side effects, and pass/fail result. This evidence makes a finding reproducible and suitable for regression testing.
6. Test capabilities beyond prompts
Extend the matrix when these capabilities exist in the system under assessment. Keep every scenario authorized, bounded, and isolated.
- Memory: check whether untrusted instructions persist or are reused as trusted preferences in later tasks.
- RAG: check whether poisoned or conflicting content changes planning, data access, or tool selection.
- MCP and tool protocols: verify that tool metadata, parameters, identity, and authorization are validated independently of the model.
- Browser or computer use: check whether untrusted page content can influence navigation or high-impact actions.
- Coding actions: check whether generated or retrieved instructions can trigger unauthorized execution or access beyond the approved workspace.
- Supply-chain connections: include connected tools, plugins, dependencies, and data sources in the trust-boundary review.
- Inter-agent communication: check whether one agent can pass untrusted instructions or excessive authority to another.
Do not add categories merely because they are common elsewhere. Test them when the target agent actually has those capabilities.
7. Measure and report findings
Use attack success rate carefully
Attack Success Rate (ASR) is the number of successful attacks divided by the total number of attacks:
ASR = successful attacks ÷ total attacks × 100
Report ASR with:
- Coverage: components, workflows, identities, tools, and attack categories tested
- Severity and impact: data, permissions, or actions exposed
- Exploitability: how readily the behavior is reproduced within the approved boundary
- Reproducibility: whether the same case produces the same result
- False positives: findings not confirmed by the execution trace or controls
- Time to compromise: how long or how many steps were required to reach the unsafe outcome
- Control bypass: whether a permission check, safeguard, rate limit, or approval was bypassed
Generated attacks and model-based evaluations can be nondeterministic. Keep the test set, model version, configuration, prompts, and evaluation rules fixed when comparing rounds, and label regenerated cases clearly.
Use a consistent finding record
Every confirmed finding should include:
- Objective and asset: the behavior, model component, memory, RAG source, tool, API, permission, workflow, or action assessed
- Attack category: injection, leakage, poisoning, tool misuse, authorization, data exposure, or excessive agency
- Expected behavior: the safe outcome and required approval state
- Observed behavior and evidence: inputs, outputs, retrieved content, calls, permissions, and side effects
- Impact, severity, and exploitability: the consequence and how readily it can be reproduced
- Owner and remediation: the responsible team, proposed control, and status
- Retest status: whether the fix was verified and added to the regression suite
Prioritize findings by impact, severity, exploitability, reproducibility, affected data or actions, deployment context, and whether a safeguard or approval was bypassed.
8. Remediate the agent and its integrations
Many AI-agent vulnerabilities cannot be solved reliably by changing the prompt alone. Apply layered controls around tools, data, identity, and execution:. For a broader control checklist, see the AI agent security checklist.
- Least-privilege permissions and scoped credentials
- Deterministic authorization at tool servers or gateways
- Identity and resource-ownership checks enforced outside the model
- Strict tool schemas, allowlists, and parameter validation
- Isolation for tools, data, and high-risk execution
- Filtering, guardrails, runtime monitoring, and rate limits
- Data protections that limit sensitive information in retrieval, tool responses, logs, and output
- Human approval gates for high-impact or irreversible actions
After remediation, rerun the original case and inspect the execution trace. A safer final answer is not enough if the agent still performs the unsafe action internally or if a connected tool accepts an unauthorized request.
A compact remediation example
Suppose a bounded staging test shows that untrusted retrieved content changes a planned tool call. Record the retrieved content, plan, tool parameters, authorization decision, and side effect. Then add controls at the retrieval, planning, and tool-authorization boundaries, rerun the same case, and add the confirmed failure to the regression suite. The retest must verify both the final response and the underlying execution trace.
9. Retest continuously
Convert every confirmed failure into a reproducible regression test. Retest after changes to:
- The model or model-serving configuration
- System prompts, policies, or guardrails
- Retrieval configuration, documents, memory, or data
- Tools, plugins, MCP servers, APIs, or integrations
- Permissions, credentials, identity checks, or approval paths
- Agent workflows and other configuration affecting external actions
Maintain targeted cases for known weaknesses alongside broader recurring campaigns. The goal is a continuous loop: scope, map, test, measure, remediate, and test again.
Practical authorized AI-agent red-team checklist
Before testing
- Confirm ownership or explicit authorization.
- Define scope, rules of engagement, stop conditions, rate limits, logging, and rollback boundaries.
- Use a non-production or controlled environment with synthetic or approved data.
- Prepare scoped credentials, monitoring, and constrained or reversible actions.
- Inventory prompts, memory, RAG, tools, APIs, permissions, approvals, identities, and external side effects.
- Create an attack matrix covering injection, leakage, poisoning, tool misuse, authorization, data exposure, and excessive agency.
During testing
- Run manual and automated single-turn and multi-turn cases.
- Cover direct and indirect prompt injection, jailbreaks, instruction leakage, context poisoning, manipulated parameters, unauthorized tool sequences, privilege escalation, data exposure, and approval bypass.
- Capture prompts, history, retrieved content, outputs, tool calls, permissions, approval state, side effects, and pass/fail results.
- Stop at the defined boundary and do not access unrelated live systems or real customer data.
After testing
- Validate automated findings manually against the execution trace.
- Calculate ASR alongside coverage, severity, exploitability, reproducibility, false positives, and time to compromise.
- Prioritize confirmed findings and apply layered defensive controls.
- Rerun failed cases and verify that authorization and side effects are safe.
- Convert confirmed failures into regression tests and retest after relevant changes.
The safest effective process is not a collection of jailbreak attempts. It is an authorized, evidence-driven assessment of the entire AI agent and its ability to interpret instructions, use data, invoke tools, follow permissions, and act.