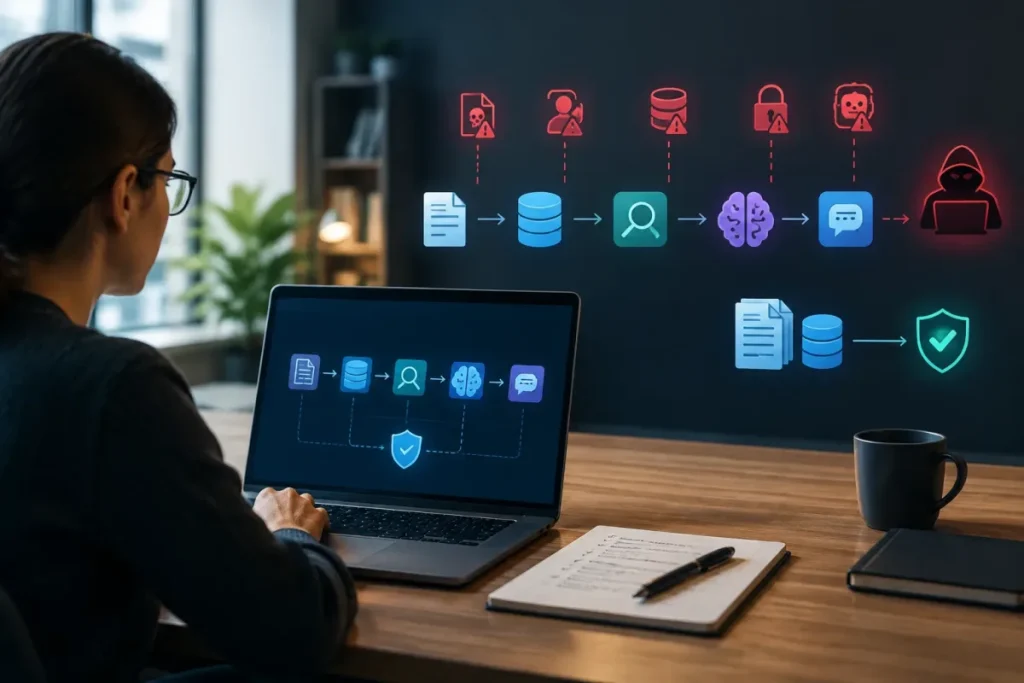

RAG red-team workflow
- Red team a RAG application by first mapping and scoping the full pipeline, then conducting authorized tests for knowledge-base poisoning, indirect prompt injection, retrieval/context manipulation, data leakage and access-control bypasses, and unsafe model or tool behavior; record expected versus actual results, remediate, and retest.
- Use a staged or explicitly authorized endpoint and define success criteria before testing.
- Create adversarial documents and queries that target ingestion, ranking, retrieval, context assembly, and generation separately.
- Verify that retrieved content cannot override higher-priority instructions or trigger unauthorized actions.
- Probe for PII, confidential records, cross-user or cross-tenant retrieval, and citation or grounding failures.
Red team a RAG application by first mapping and scoping the full pipeline, then conducting authorized tests for knowledge-base poisoning, indirect prompt injection, retrieval and context manipulation, data leakage and access-control bypasses, and unsafe model or tool behavior. Record results, remediate, and retest.
Test the entire RAG application
RAG red teaming is an application-level security assessment, not just a set of adversarial prompts for the language model. Test the connected system from source data and ingestion through chunking, embeddings, vector storage, retrieval, context assembly, generation, guardrails, identities, permissions, citations, and tools. For a broader comparison of AI red teaming and penetration testing, see the related guide.
Use a staging endpoint or an explicitly authorized environment. Establish normal behavior, test each layer in a controlled way, compare expected with actual results, preserve evidence, apply the mitigation at the layer that failed, and rerun the relevant tests.
The five-step workflow
- Authorize and scope: define the endpoint, identities, data boundaries, rules of engagement, success criteria, and stop conditions.
- Map and baseline: document the full RAG data flow and capture retrieval, context, answer, citation, permission, and tool telemetry.
- Test the attack surfaces: assess ingestion poisoning, direct and indirect prompt injection, retrieval manipulation, leakage, and authorization boundaries.
- Evaluate behavior: separate retrieval, generation, and full-pipeline results, including tool or agent actions where applicable.
- Remediate and retest: record evidence, fix the affected layer, and run category-specific regression tests.
Prepare authorization, scope, and safeguards
Set the rules of engagement
Before creating adversarial documents or queries, define:
- The approved endpoint, environment, testing period, systems, and components in scope.
- The approved test identities, tenant contexts, and data boundaries.
- The security properties under evaluation: confidentiality, integrity, authorization, availability, and safe tool behavior.
- Expected secure behavior and acceptance criteria for each test.
- Stop conditions, escalation contacts, logging requirements, and evidence-handling procedures.
Use test data wherever possible. Do not attempt unauthorized access, real-data exfiltration, persistence, or operational disruption. If a test could affect an external system, obtain explicit approval and use a mock target, dry-run mode, or other safe substitute.
Red teaming is appropriate only when it is authorized and governed by the organization’s rules, agreements, and applicable requirements. This is defensive testing guidance, not permission to probe systems you do not control.
Define identities, access scope, and stop conditions
Create approved test identities representing different users and tenants, with intentionally different document permissions. Record the identity and access scope for every query. This supports cross-user and cross-tenant testing without using another customer’s real information. For additional guidance on Identity and Access Management for AI Applications, see the dedicated guide.
Stop when a test suggests exposure of sensitive data, unexpected external communication, destructive tool behavior, or loss of service. A controlled assessment should reveal weaknesses without becoming the incident it is intended to prevent.
Map the pipeline and establish a baseline
Map components and trust boundaries
Draw the data flow from source to response and mark each trust boundary. Include:
- Source systems, uploads, connectors, and ingestion jobs.
- Parsing, normalization, chunking, metadata, and permission labels.
- Embeddings, vector storage, indexes, metadata filters, and caches.
- Query handling, ranking, reranking, retrieval limits, and context assembly.
- System instructions, user input, retrieved content, model generation, and guardrails.
- User and service identities, tenant boundaries, and authorization decisions.
- Tools, APIs, external messages, and other actions available to an agentic RAG system.
For every boundary, ask what is trusted, what is untrusted, who can modify it, and which authorization decision must occur before data crosses it. Treat retrieved content as untrusted context, even when it comes from an internal knowledge base.
Capture normal behavior and telemetry
Run ordinary approved queries before adversarial testing. Capture enough information to distinguish a retrieval failure from a context, model, policy, or tool failure:
- Query, identity, tenant, access scope, application version, and model version.
- Retrieved documents and chunks, metadata filters, ranking, and scores where available.
- The assembled context and the order in which content was presented.
- Answer text, citations, source identity, refusals, and guardrail events.
- Tool calls, parameters, authorization decisions, results, and external actions.
Define secure expected behavior before each test. An unauthorized document should not enter the model context, even if a final-answer filter prevents direct disclosure. Retrieval-time enforcement is stronger than relying only on response filtering.
Run the core RAG security tests
1. Test ingestion and knowledge-base integrity
Use controlled adversarial documents in the approved environment. Determine whether manipulated content is ingested, retained, made eligible for retrieval, ranked, and able to influence an answer.
Test document, data, retrieval, and vector-poisoning scenarios without changing model weights. Vary one factor at a time, such as document location, metadata, chunking, or expected relevance. Measure:
- Whether the document enters the index and remains after ingestion.
- Whether its chunks receive the expected metadata and permissions.
- Whether it is retrieved for relevant and irrelevant queries.
- Whether it changes ranking, assembled context, citations, or generated answers.
- Whether correction or removal propagates to indexes and caches.
A secure result is not simply that the model ignored the document. The system should also control which content becomes retrievable and prevent untrusted material from acquiring inappropriate authority.
2. Test direct and indirect prompt injection
Direct prompt injection places adversarial instructions in the user query. Indirect prompt injection places untrusted instructions in a document the application retrieves. Test them separately to identify whether the weakness is in input handling, retrieval, context assembly, instruction priority, or model behavior.
Use safe test objectives rather than operational exploit payloads. Check whether the application follows the approved task instead of a retrieved instruction, protects restricted test content, preserves instruction priority, and prevents an unapproved action.
Vary one factor at a time:
- Instruction placement in the query or document.
- Retrieval rank and chunk position.
- The number of surrounding chunks and total context size.
- Quoted, cited, duplicated, or mixed content.
- Single-turn and multi-turn interaction.
- Encoding variations and other approved adversarial input forms.
Retrieved text should remain data, not become a new system authority. A failure occurs when retrieved content overrides higher-priority instructions, discloses protected information, bypasses safeguards, or causes an unauthorized action.
3. Test retrieval manipulation and context assembly
Assess whether query handling, ranking, chunk boundaries, filters, and context ordering produce an unsafe model input. Test:
- Partial passages and misleading chunk boundaries.
- Duplicate or competing content.
- Context-window overflow and displacement of important instructions.
- Changes in retrieval rank and surrounding context.
- Whether retrieved text receives inappropriate authority over system instructions.
- Whether citations reflect the content actually used.
Test provenance as well. The application should not fabricate a citation, misidentify its source, cite content that was not used, or expose a source that the querying identity is not authorized to see.
Test authorization, isolation, and leakage
Validate tenant and permission boundaries
Use approved identities to query documents that should be available, unavailable, recently revoked, and recently deleted. Verify the result at the retrieval layer, not only in the final answer.
| Test area | Expected secure behavior | Evidence to capture |
|---|---|---|
| Cross-user and cross-tenant retrieval | Only authorized chunks enter context. | Identity, tenant, returned chunk IDs, filters, and context trace. |
| Metadata and chunk permissions | Permission filters are enforced consistently. | Permission attributes, retrieval decision, ranking, and citations. |
| Revocation | New requests cannot retrieve content after access is removed. | Revocation time, query time, cache state, and retrieval result. |
| Deletion propagation | Deleted content is absent from indexes, context, and citations. | Deletion event, index state, cache state, and later traces. |
| Stale caches | Cached results do not bypass current permissions. | Cache key, identity scope, age, invalidation event, and output. |
A cross-tenant retrieval failure exists when one tenant’s content enters another tenant’s model context, even if the final answer appears harmless. Stop if the test could expose real sensitive information.
Test leakage and knowledge extraction
Use approved, bounded queries to test direct disclosure and gradual reconstruction. Cover:.
- PII and confidential test records.
- Hidden prompts, system instructions, and configuration details.
- Systematic knowledge extraction through sequenced queries.
- Unauthorized citations, source identity, and provenance.
- Fabricated citations or answers attributed to the wrong source.
- Outbound actions involving sensitive content, only against an explicitly approved mock destination.
Keep security measurements separate from answer quality. A fluent answer can still represent a security failure if it used unauthorized context, disclosed protected content, or cited a restricted source. For practical controls focused on preventing LLM data leakage, see the related checklist.
Test model, guardrails, and agent behavior
Test jailbreaks and multi-turn attacks
Use manual and automated probes for jailbreaks, encoding variations, conflicting instructions, multi-turn pressure, and relevant guardrail behavior. Evaluate whether restricted content remains protected, instruction priority is preserved, refusals are safe, and authorization remains effective throughout the conversation.
Bound guardrail and availability testing
Where availability is in scope, test whether repeated adversarial interactions or safety-triggered refusal behavior consume excessive context or resources, create refusal loops, or prevent legitimate approved requests. Set request limits, resource boundaries, monitoring, and stop conditions before running these tests.
The objective is to measure whether the service preserves availability under agreed limits, not to disrupt production or exhaust operational resources.
Test tool and agent execution
For agentic RAG, verify that retrieved instructions cannot trigger unauthorized tool calls, external messages, or other actions. Prefer mock tools, dry-run modes, or explicitly approved targets. For a focused treatment of AI agent tool misuse, see the related guide.
Evaluate tool events independently from the text response. Capture the requesting identity, retrieved instruction, tool name, parameters, authorization decision, result, and external effect. An acceptable answer does not make an unsafe tool call acceptable.
Separate component tests from full-pipeline tests
Run three related test types:
- Retrieval-only: verify which documents and chunks are eligible, returned, ranked, and filtered.
- Generation-only: provide controlled context to evaluate model and guardrail behavior.
- Full-pipeline: connect query processing, retrieval, context assembly, generation, citations, and tools.
Component isolation helps identify where a weakness originates before confirming its end-to-end impact. Keep separate measures for unauthorized retrieval, injection resistance, poisoning, citation provenance, answer quality, and unsafe tool actions.
Automate repeatable testing
Automation should support the methodology, not replace it. Maintain a versioned adversarial corpus containing approved documents, queries, identities, expected outcomes, and test metadata. Add deterministic assertions such as:
- Restricted chunk identifiers never enter context for an unauthorized identity.
- Retrieved instructions cannot override higher-priority safeguards.
- Deleted or revoked content is not returned or cited.
- Citations match available, authorized source records.
- Disallowed tool calls are blocked and recorded.
Run high-risk checks in CI and use release gates for changes to retrieval, prompts, permissions, ingestion, guardrails, tools, or models. Update the test corpus after incidents and meaningful architecture changes. Use human review when automated grading cannot reliably assess authorization, provenance, or subtle context failures.
Choose tools by test objective
There is no universally best red-team tool. Choose according to the application layer being tested, the visibility needed into retrieval and context, the grading approach, and the existing automation workflow. For examples of tools used to secure agentic systems, see AI agent security tools.
| Option | Use it as | Important boundary |
|---|---|---|
| Promptfoo | An application-layer RAG testing option, including custom provider configuration. | It supports the methodology but does not replace pipeline mapping, authorization tests, or human review. |
| Azure AI Evaluation SDK | An implementation option where it fits the existing evaluation workflow. | It is not a prerequisite for an assessment. |
| Garak, PyRIT, DeepTeam, Giskard/RAGET, and ARTEMIS | Candidate tools or frameworks to investigate for relevant AI or RAG red-team work. | Capabilities and RAG-specific coverage are not identical; validate fit against the test matrix. |
Whatever tool you select, it should feed the same controlled process: approved identities and data, captured traces, explicit expected outcomes, secure evidence handling, remediation, and regression testing.
Report findings, remediate, and retest
Use a consistent finding record
Record every finding with:
- Affected pipeline layer and vulnerability category.
- Test identity, tenant, endpoint, environment, and access scope.
- Reproduction steps using approved test data.
- Expected versus actual behavior.
- Retrieved chunks, context evidence, citations, model output, and tool events.
- Severity and affected security property.
- Mitigation owner, change made, and acceptance criteria.
- Regression tests run and their results.
| Finding field | What to document |
|---|---|
| Affected layer | Ingestion, retrieval, context, generation, authorization, guardrails, or tools. |
| Identity and scope | User, tenant, permissions, endpoint, environment, and application version. |
| Evidence | Queries, document manifest, retrieved chunks, context, citations, answers, and tool traces. |
| Expected versus actual | The secure behavior and the observed deviation. |
| Mitigation | The control changed and the category-specific acceptance criteria. |
| Regression result | Tests rerun, versions used, and whether the issue remains fixed. |
Apply the mitigation at the layer that failed. A retrieval authorization problem requires retrieval-time enforcement, not only a final-answer filter. After the fix, rerun the original test and related variants, including revoked, deleted, cached, and cross-tenant content where applicable.
Final retest checklist
- Controlled adversarial content is ingested, ranked, and retained only as intended.
- Retrieved instructions cannot override higher-priority safeguards.
- Cross-user and cross-tenant isolation holds at retrieval time.
- Metadata and chunk-level permissions are enforced.
- Revoked and deleted content stays out of retrieval, context, and citations.
- Stale caches do not bypass current authorization decisions.
- PII, confidential information, hidden prompts, and extracted knowledge remain protected.
- Citations identify authorized sources and preserve provenance.
- Tool calls cannot perform unauthorized actions or send unapproved external messages.
- High-risk tests run again after relevant code, data, prompt, policy, model, or retrieval changes.
A RAG red-team assessment is incomplete until mitigation has been validated. Preserve the evidence, rerun the relevant category, and confirm that the fix protects the full application rather than only its final text response.