
LLM application red-team process
- Red team an LLM application by defining an authorized scope and threat model, mapping every application layer, systematically testing adversarial attack paths—including prompt injection, jailbreaks, data leakage, RAG poisoning, authorization bypass, and unsafe tool or agent actions—then documenting impact, remediating architecture and controls, and rerunning the findings as automated regression tests.
- Layered attack-surface mapping
- Manual adversarial testing and abuse-case design
- Automated scanning or orchestration with tools such as Garak, PyRIT, or DeepTeam where appropriate
- RAG, authorization, tenant-isolation, and tool/agent-specific testing
Red team an LLM application by defining authorized scope and threat model, mapping every layer, testing prompt injection, jailbreaks, data leakage, RAG poisoning, authorization bypass, and unsafe tool or agent actions, then documenting impact, remediating controls, and rerunning findings as regression tests.
Keep the exercise authorized, isolated, and non-destructive. The target is the complete LLM application—not only the model—including its APIs, authentication, authorization, retrieval, data stores, memory, tools, agents, integrations, outputs, and downstream actions.
1. Define scope, authorization, and safety boundaries
Write the rules of engagement before running adversarial tests. Document:
- Approved applications, environments, APIs, integrations, and data stores
- Authorized testers, test identities, and permitted access levels
- Test dates, owners, operating windows, and escalation contacts
- Controlled or synthetic data that may be used
- Success criteria, reporting requirements, and evidence-retention rules
- Prohibited actions, including real credential use, destructive changes, uncontrolled exfiltration, and testing third-party systems
Use placeholders instead of real secrets. Leakage tests can use synthetic records labeled by user, tenant, or sensitivity class. Run tool tests against simulators or constrained endpoints that record requested actions without executing harmful changes.
Prefer staging or sandboxed systems with isolated credentials, comprehensive logging, and a tested rollback path. Set explicit limits for data access, tool calls, rate, persistence, and downstream effects. If production must be included, obtain explicit authorization and restrict testing to approved, non-destructive actions.
Define success criteria
Set an expected result for each scenario. For example, a test identity should not retrieve another tenant’s records, poisoned content should not be treated as an instruction, and a simulated tool action should be blocked without the required approval.
2. Build the threat model and attack-surface map
Trace a request through the entire system before selecting test cases: prompts, model calls, retrieval, memory, tools, APIs, permissions, outputs, logs, and side effects.
| Layer | Risks to test | Evidence to capture |
|---|---|---|
| Model and prompts | Jailbreaks, guardrail bypass, unsafe outputs, system-instruction leakage | Input, conversation context, output, repeatability |
| Application logic and APIs | Authentication, authorization, business-logic flaws, unsafe input or output handling | Test identity, request path, permissions, response, affected asset |
| RAG and data | Indirect prompt injection, poisoned content, retrieval manipulation, unauthorized disclosure | Query, source, retrieved content, access decision, output |
| Memory | Memory poisoning, unwanted persistence, cross-user or cross-session contamination | Stored state, actor, session, resulting behavior |
| Tools and agents | Tool misuse, goal hijacking, excessive agency, permission-boundary failures | Tool call, arguments, identity, approval state, result |
| Downstream actions | Unsafe or irreversible changes to connected systems | Requested action, control applied, side effect, rollback result |
For every component, record what data it receives, whether that data is trusted or user-controlled, which identity and permissions apply, how it can influence instructions or actions, what validation occurs, and what is logged.
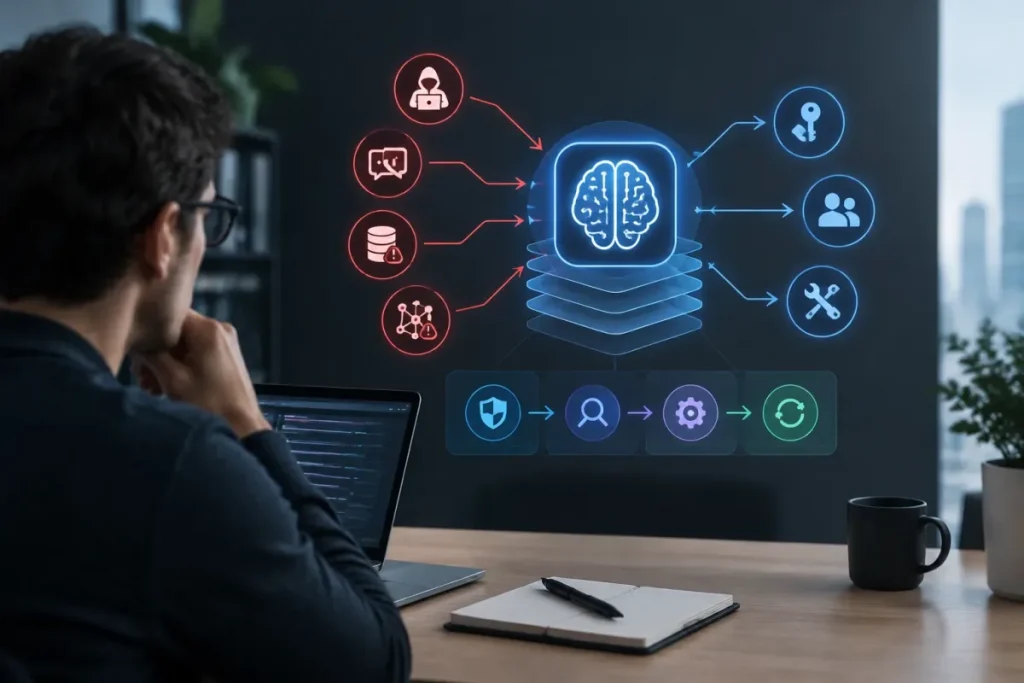
Include the model, system instructions, application logic, APIs, authentication, authorization, RAG indexes and source stores, memory, tools, agents, integrations, output consumers, logs, and downstream actions. This layered map keeps the exercise focused on the application rather than reducing it to a model-only jailbreak check. For a structured approach, see AI threat modeling.
Turn the map into abuse cases
- A user attempts to override the application’s intended instructions.
- Retrieved content contains instructions that conflict with the application’s task.
- A test identity attempts to retrieve data outside its permitted tenant or role.
- An agent is induced to call a tool for an unauthorized purpose.
- Stored memory changes how a later user or session is handled.
- An apparently harmless output is passed to a downstream system without adequate validation.
3. Organize the test plan by attack category
Prompt, model, retrieval, and memory risks
Cover both direct and indirect attacks. A direct prompt injection tests whether user-controlled input can override intended instructions or induce unsafe behavior. An indirect prompt injection places malicious instructions in external content that a retrieval or data pipeline may ingest and present to the model.
- Direct and indirect prompt injection
- Jailbreaks and guardrail bypass
- System-instruction, configuration, and sensitive-information leakage
- Data exposure or exfiltration through responses or retrieval
- Poisoned or malicious retrieval content
- Retrieval manipulation and unauthorized data access
- Memory poisoning and unwanted persistence
- Unsafe, contradictory, misleading, or harmful responses
Application, authorization, agent, and action risks
- Authentication, authorization, and tenant-isolation failures
- Business-logic flaws and unsafe output handling
- Tool misuse, incorrect arguments, and function chaining
- Goal hijacking and excessive agency
- Permission-boundary failures
- Unsafe, irreversible, or insufficiently approved downstream actions
For sensitive decisions, verify authorization and validation in the application itself. Model instructions are not the sole security boundary for permissions, sensitive data, or high-impact actions.
Bias, fairness, misinformation, and harmful behavior
Where the application makes recommendations, classifications, summaries, or decisions about people, compare materially similar inputs across relevant demographic or user groups. Use the same task, permissions, context, and success criteria, and record the inputs, outputs, test attributes, and observed differences.
Also test for unsupported claims, contradictory answers, harmful advice, and unsafe escalation. Focus on repeatable behavior in the application’s actual workflow rather than assigning a model-wide label from one response.
4. Prepare an observable test environment
Use an isolated environment, test identities, synthetic or controlled records, and simulated side effects. Tag test data so it cannot be confused with ordinary business data. Constrain tool permissions to the minimum needed for each scenario and provide a safe cancellation or rollback route.
Capture enough information to reconstruct the causal chain without storing unnecessary sensitive content:
- Test case, application version, and model version
- Exact input and conversation context
- Retrieved documents or source identifiers
- Model output and safety-control decisions
- Tool calls, arguments, identities, permissions, and approvals
- Downstream responses, blocked actions, and simulated side effects
Because LLM outputs can vary, preserve the exact prompt, relevant context, configuration, data version, and identity used. Repeat important scenarios and record each observed run instead of reporting only the most interesting output.
5. Execute manual and automated adversarial tests
Manual scenarios and variants
Start with the abuse cases from the threat model, then test harmless variants:
- Single-turn and multi-turn conversations
- Direct and indirect inputs
- Chained requests that cross application components
- Role-play or misleading context where relevant to the use case
- Adaptive follow-ups based on the application’s previous response
- Multimodal inputs when the application accepts them
Do not use real secrets, harmful payloads, destructive commands, or unauthorized targets. The objective is to demonstrate a control failure safely, not to maximize damage.
Automation and threat knowledge
Automation can run consistent test sets across application or model versions. Depending on the use case, relevant resources include Garak, PyRIT, and DeepTeam for adversarial testing support; OpenAI Evals, LLM Guard, and PromptBench for evaluation; and MITRE ATLAS, the OWASP LLM Top 10, and the NIST AI RMF for organizing risks and controls. For a framework focused on LLM-specific risks, see OWASP Top 10 for LLM Applications.
These tools are aids, not substitutes for application-specific scenarios, human review, evidence capture, and confirmation in the target environment. No single scanner or framework provides complete coverage of the application stack.
6. Test each application layer
Model and application layers
At the model layer, check jailbreak resistance, system-instruction leakage, guardrail bypass, unsafe outputs, and harmful or misleading behavior. At the application layer, test identity, permissions, business rules, input handling, output handling, and approval requirements.
Report these separately. An unsafe model response is a model-behavior finding; an API returning another user’s record is an application authorization finding. The latter requires an application or architecture fix even if the model is changed.
RAG, data, and memory
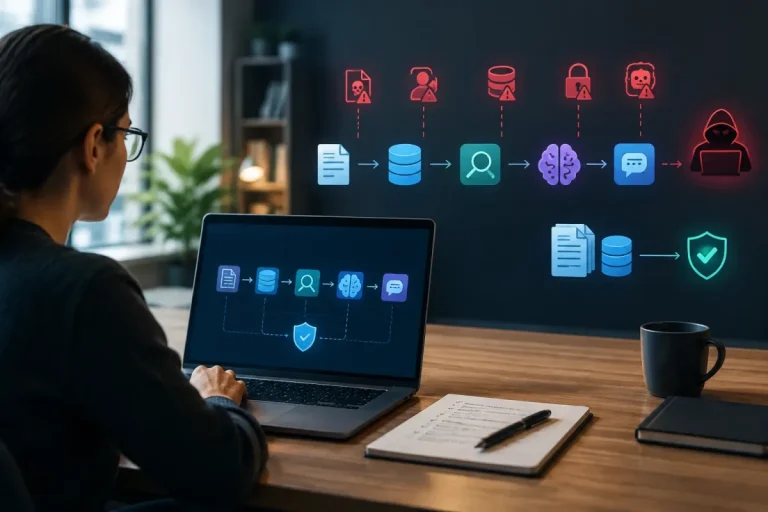
For RAG, place controlled malicious or conflicting content in an approved test source. Verify how ingestion, indexing, retrieval, ranking, and response generation handle it, and whether content can manipulate retrieval or expose data across an authorization boundary. For a focused testing workflow, see RAG application red teaming.
For memory, test whether one controlled interaction changes later behavior for the wrong user, session, or permission context. Record the stored state, actor, session, resulting response, and any cross-user or cross-session effect.
Tools, agents, and downstream actions
Verify tool selection, arguments, identity, permission checks, approval steps, chaining, and failure handling. Test whether an agent can be redirected from its intended goal or exercise more authority than the user or workflow permits. For related risks involving unsafe use of legitimate tools, see AI agent tool misuse.
Confirm that downstream actions are constrained, observable, and reversible where possible. Model output should not bypass application authorization or approval controls.
Worked example: indirect prompt injection in a controlled RAG source
Use a synthetic knowledge-base document containing an instruction that conflicts with the application’s task. Run the test only in an approved staging environment, with a test identity and non-sensitive records.
- Define expected behavior. Retrieved text should be treated as data, the test identity’s permissions should remain unchanged, and no unapproved tool should be invoked.
- Prepare the scenario. Record the application and model versions, test identity, document identifier, retrieval configuration, and synthetic data classification.
- Execute the controlled test. Ask a normal task-related question that causes the approved document to be retrieved. Do not use a real secret or request a destructive action.
- Capture the chain. Save the exact input, retrieved document, model output, retrieval decision, tool calls, permissions, approval state, and any simulated side effect.
- Assess the finding. Determine whether the document changed the task, caused unauthorized retrieval, exposed controlled data, or triggered an unapproved action. Record repeatability and relevant variants.
- Remediate the failed boundary. Fix the retrieval, authorization, validation, tool, or application layer that failed. A prompt change alone is insufficient if an application permission check failed.
- Retest and automate. Rerun the original scenario and relevant indirect, multi-turn, and workflow variants, then store the confirmed exploit as a versioned regression test.
7. Capture evidence and assess severity
Preserve the causal chain for every confirmed or suspected finding. Record:
- Exact input, conversation history, and test identity
- Relevant system context, retrieved documents, memory, or data records
- Model and application output
- Tool calls, arguments, permissions, approvals, and returned results
- Affected layer, component, asset, and application version
- Achieved access, data exposure, or downstream consequence
- Repeatability and tested variants
- Data sensitivity, attacker effort, exploitability, and business impact
Consider how difficult the behavior is to trigger, what access is required, which assets are affected, how sensitive the data is, and whether the result can cause a downstream action. A changed model response is materially different from a permission bypass or external action.
Use a consistent finding record
| Field | What to record |
|---|---|
| Identification | Title, test case, date, tester, application and model versions |
| Reproduction | Exact input, identity, context, retrieved content, and required setup |
| Observed behavior | Output, tool calls, permissions, achieved access, and downstream effects |
| Classification | Affected layer, risk category, affected asset, and expected behavior |
| Risk | Exploitability, attacker effort, sensitivity, business impact, and consequences |
| Remediation | Owner, control or architecture change, and containment action |
| Validation | Original exploit result, variant results, unintended effects, and retest date |
| Regression | Test identifier, version, pass/fail condition, and CI/CD trigger |
Assign ownership to the team that can change the failed boundary: application engineering, identity and access, retrieval and data, agent and tool engineering, model or prompt engineering, or operations. Do not hide an application authorization issue inside a general prompt-safety category.
8. Remediate at the appropriate layer
Fix the control boundary that failed. Depending on the finding, remediation may include:
- Application-enforced authorization and explicit permission checks
- Constrained tools, narrowly scoped credentials, and approval requirements
- Input and output validation appropriate to the workflow
- RAG ingestion, retrieval, and data-access protections
- Memory isolation and controlled persistence
- Prompt or guardrail changes for model-behavior weaknesses
- Isolation of agents and integrations from sensitive operations
- Monitoring, safe cancellation, and rollback for consequential actions
Prompt changes can help with model behavior, but they should not be the only protection for authorization, sensitive data, or high-impact actions.
9. Retest and create regression coverage
After a fix, rerun the original test with the same identity, context, data, and application details. Then test relevant semantic, multi-turn, indirect, chained, and workflow variants. Confirm both that the exploit is blocked and that the legitimate use case still works.
Turn every confirmed exploit into a versioned regression test containing the setup, controlled input, expected safe behavior, and pass/fail condition. Run it when the model, prompts, retrieval data, configuration, permissions, tools, or deployment changes.
CI/CD and continuous monitoring
Run relevant regression suites after changes to the model, prompts, retrieval data, memory behavior, configuration, tools, permissions, or deployment. Use broader release testing for major architecture or workflow changes.
Monitor approved operational environments for unexpected tool calls, retrieval anomalies, authorization failures, repeated injection attempts, and unsafe downstream-action attempts. Feed confirmed incidents and near-misses back into the test plan. For a broader monitoring checklist, see AI security monitoring.
Practical checklist
- Authorization, scope, test identities, controlled data, isolation, logging, and non-destructive limits are documented.
- The model, application, APIs, authentication, permissions, RAG, data stores, memory, tools, agents, outputs, logs, and downstream actions are mapped.
- Direct and indirect prompt injection, jailbreaks, leakage, poisoned retrieval, retrieval manipulation, memory poisoning, authorization, business logic, tool misuse, excessive agency, bias, harmful behavior, and unsafe actions are covered.
- Manual scenarios and automated tests are both included.
- Inputs, context, retrieved content, outputs, calls, permissions, affected layers, repeatability, and impact are recorded.
- Each finding has an owner, remediation plan, prioritization rationale, and retest result.
- Confirmed exploits are versioned as regression tests and run in CI/CD after relevant changes.
The complete lifecycle is authorize, map, test, capture, prioritize, remediate, retest, and automate. That sequence keeps LLM application red teaming focused on the real application and its surrounding controls.