
LLM red-teaming checklist at a glance
- An effective LLM red-teaming checklist should cover scope and authorization, architecture and threat modeling, model and application attacks, RAG and data-isolation risks, agent and tool misuse, responsible-AI harms, and the full findings-to-remediation-to-retest lifecycle.
- Use a layered checklist spanning model, application, RAG, agent/tool, and responsible-AI risks.
- Create reproducible adversarial scenarios and measure pass/fail outcomes against defined acceptance criteria.
- Integrate repeatable adversarial tests into CI/CD where appropriate, using tools such as Promptfoo, PyRIT, or DeepTeam as implementation options rather than mandatory requirements.
- Retest every remediated finding before release and after material system changes.
An effective LLM red-teaming checklist should cover scope and authorization, architecture and threat modeling, model and application attacks, RAG and data-isolation risks, agent and tool misuse, responsible-AI harms, and the full findings-to-remediation-to-retest lifecycle.
LLM red teaming assesses the authorized, assembled AI system—not only the base model. Adapt the checklist to the deployment: a customer-facing assistant, RAG application, and tool-using agent do not expose identical risks.
What an LLM red-teaming checklist covers
Red teaming searches for unexpected failure modes, while an evaluation scores predefined test cases against expected outcomes. Conventional penetration testing is complementary, but an LLM red-teaming checklist must also examine prompts, model behavior, retrieval, application logic, tools, agents, memory, connected systems, and output paths.
Keep testing authorized, isolated, scoped, and documented. Use controlled environments and approved test data, and define escalation procedures before testing scenarios that could expose sensitive information or trigger business actions.
1. Establish authorization, scope, and success criteria
Begin with an engagement charter that defines what may be tested, how it may be tested, and what constitutes an unacceptable result.
- ☐ Identify target systems, environments, models, versions, interfaces, and connected services.
- ☐ Obtain written authorization and define scope boundaries, access permissions, testing windows, and prohibited outcomes.
- ☐ Identify security, engineering, risk, legal, compliance, ethics, business, and relevant domain stakeholders.
- ☐ Define objectives, success criteria, escalation contacts, and stop conditions, and communication channels.
- ☐ Isolate testing from production where possible and specify how sensitive test data will be handled.
- ☐ Agree how findings will be prioritized, risk-accepted, remediated, and retested.
Do not begin with unrestricted experimentation. The rules of engagement should state what testers may access, what actions they must not perform, and how potentially harmful or high-impact results are reported.
Red team and blue team: how they differ
The red team searches for exploitable or harmful behavior through authorized adversarial testing. The blue team focuses on defensive readiness: monitoring, detection, response, hardening, containment, and recovery. The activities complement each other: red-team findings are more useful when defensive teams can observe, investigate, and address them.
2. Inventory the complete AI attack surface
Build an architecture and data-flow map before designing scenarios. The target is the complete application, not an isolated model endpoint.
- ☐ Model, model version, inference endpoint, system prompts, policies, and guardrails.
- ☐ User interfaces, APIs, application logic, authentication, authorization, and integrations.
- ☐ RAG sources, ingestion pipelines, embedding services, vector stores, retrievers, filters, and citations.
- ☐ Tools, agents, external services, business actions, and connected data stores.
- ☐ Conversation memory, state, context windows, inter-agent communication, and handoffs.
- ☐ Input types, uploaded files, external content, rendering, response delivery, logging, and output paths.
- ☐ Trusted and untrusted content boundaries, credentials, tokens, secrets, and sensitive-data flows.
Mark where user-controlled or externally retrieved content can influence instructions, tool selection, retrieved context, memory, or downstream actions.
3. Prioritize risks and define acceptance criteria
Prioritize testing according to the system’s actual exposure and authority. Consider:
- Customer or employee exposure and the sensitivity of accessible data.
- Autonomy, business actions, external side effects, and cross-system access.
- Likelihood, potential impact, severity, and the ability to detect or contain a failure.
- Legal, regulatory, ethical, contractual, financial, or reputational consequences.
For each test family, define a pass, fail, or inconclusive result before testing. Acceptance criteria should be deployment-specific. For example, a test may pass only when an unauthorized tool action is blocked and logged, or when a sensitive-data request is refused without exposing protected content.
| Risk disposition | Use when | Release decision to record |
|---|---|---|
| Block or remediate before release | The outcome creates unacceptable exposure, unauthorized action, sensitive-data leakage, or material harm. | Release blocked, or an explicitly approved exception is documented. |
| Remediate and retest | The failure is confirmed and risk reduction is required. | Owner, fix, acceptance criterion, and retest status recorded. |
| Track or accept with controls | The issue is understood, bounded, and supported by appropriate controls or a documented risk decision. | Rationale, owner, controls, and review conditions recorded. |
| Inconclusive | The result cannot be reproduced or the test data does not establish whether the control worked. | Additional evidence or a controlled repeat test assigned. |
This is a decision worksheet, not a universal severity formula or deadline model. Apply the organization’s risk appetite and deployment requirements.
4. Run model- and prompt-layer adversarial tests
Test how the model handles conflicting, manipulative, ambiguous, and persistent instructions. Use controlled scenarios rather than treating any particular payload or attack example as universally required.
- ☐ Direct and indirect prompt injection.
- ☐ Jailbreaks, persona attacks, role changes, and progressive escalation.
- ☐ Refusal or alignment failures, including inconsistent behavior across equivalent requests.
- ☐ System-prompt extraction and exposure of hidden context, policies, or instructions.
- ☐ Memorization and leakage of PII, PHI, secrets, tokens, or other sensitive data.
- ☐ Attempts to make lower-trust content override intended instructions or controls.
- ☐ Multi-turn escalation in which individually harmless interactions create a prohibited outcome.
Record the full input sequence, relevant context, model version, response, and expected result. A single safe response does not establish resilience if the same scenario changes after additional turns or context.
5. Test application-layer risks
Application behavior can introduce weaknesses that are not visible when testing the base model alone.
- ☐ Test direct injection through user inputs and indirect injection through uploaded files, external content, and retrieved material.
- ☐ Check whether application logic passes untrusted content into privileged instructions or tool parameters.
- ☐ Test authentication, authorization, session boundaries, and integration permissions around the LLM feature.
- ☐ Check whether outputs are routed to the correct user, tenant, system, or downstream workflow.
- ☐ Review rendering and output paths for unsafe handling of generated content, without assuming a particular rendering vulnerability applies.
- ☐ Verify that errors, logs, traces, and debugging responses do not disclose hidden instructions or sensitive data.
Use normal user journeys as well as adversarial sequences. Evidence should identify whether a failure originated in the model, prompt construction, application logic, integration, or output handling.
6. Test RAG and data-isolation risks
Retrieval-augmented generation creates a security boundary between source data, retrieval controls, context assembly, and model instructions.
- ☐ Test malicious documents and document or context poisoning during ingestion.
- ☐ Verify source access controls, ingestion permissions, indexing boundaries, and tenant isolation.
- ☐ Test retrieval leakage across users, roles, datasets, and tenants.
- ☐ Check whether sensitive documents can be retrieved through direct, indirect, or repeated requests.
- ☐ Evaluate source trust, relevance, grounding, and behavior when retrieved material conflicts with application instructions.
- ☐ Verify separation between trusted reference content and attacker-controlled instructions embedded in content.
- ☐ Confirm that deletion, access changes, and data-boundary changes are reflected in retrieval behavior where applicable.
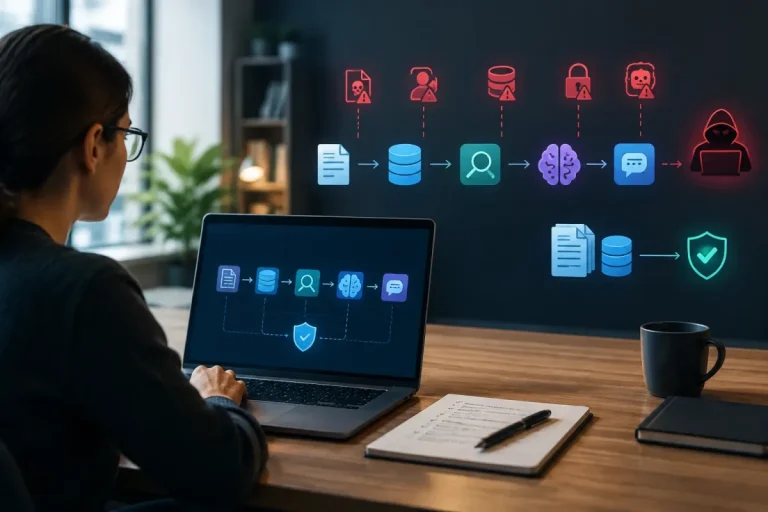
Test the full path: source, ingestion, indexing, retrieval, context assembly, model response, and output. A safe model response cannot compensate for a retrieval layer that returns data to an unauthorized requester.
7. Test agents, tools, memory, and state
Tool-using and stateful systems require tests for authority, permissions, and accumulated context—not only text responses.
- ☐ Test goal hijacking and attempts to redirect an agent from its authorized objective.
- ☐ Check excessive agency, unauthorized tool calls, permission bypasses, and actions outside the approved scope.
- ☐ Verify least-necessary access to sensitive data, external systems, files, and business functions.
- ☐ Test exposure of credentials, tokens, secrets, and tool responses.
- ☐ Check cross-system escalation and whether one tool or agent can improperly influence another.
- ☐ Test memory poisoning, context corruption, unsafe persistence, and stale or incorrect state.
- ☐ Exercise multi-turn and chained attacks across accumulated state, agent handoffs, and inter-agent communication.
Where an action can create an external side effect, define the required authorization, confirmation, logging, and containment behavior before testing it.
8. Evaluate safety, privacy, and reliability
Responsible-AI testing belongs in the same assessment because harmful or unreliable behavior can create security, customer, operational, and reputational consequences.
- ☐ Toxicity, harassment, harmful content, and unsafe responses relevant to the product.
- ☐ Bias and fairness risks across relevant use cases and populations.
- ☐ Misinformation, hallucination, factual grounding, and unsupported certainty.
- ☐ PII, PHI, secrets, tokens, retrieval leakage, and other sensitive-data exposure.
- ☐ Over-reliance in high-stakes contexts, including whether users receive adequate signals about uncertainty and limitations.
- ☐ Failure behavior when sources are missing, conflicting, stale, or untrusted.
Use single-turn, multi-turn, adaptive, document, image, and tool-output scenarios only where those modalities and workflows exist in the deployment.
Three recurring risk groups to prioritize
- Instruction and control failure: prompt injection, jailbreaks, hidden-context leakage, and refusal failures.
- Data-boundary failure: sensitive-data leakage, retrieval leakage, poisoning, and tenant-isolation failures.
- Unauthorized or harmful action: excessive agency, unsafe tool use, chained attacks, hallucination, and high-stakes over-reliance.
This grouping is a practical starting point, not a universal ranking. Priority changes with the deployment’s data, autonomy, users, and connected systems.
9. Combine manual, automated, adaptive, and multimodal testing
Combine human discovery with repeatable automation. Manual testing helps uncover application-specific chains and unexpected interactions; automated replay helps verify known failures across builds and configurations.
- ☐ Run baseline single-turn cases and relevant multi-turn stateful scenarios.
- ☐ Replay confirmed failures and meaningful technique variations.
- ☐ Test adaptive sequences in which later inputs respond to earlier outputs.
- ☐ Include documents, images, tool outputs, and external content when the system accepts them.
- ☐ Measure pass/fail outcomes against defined acceptance criteria.
- ☐ Preserve the exact model, prompt, retrieval, data, and application configuration used.
Automation expands coverage but does not prove completeness. Human review remains important for complex chains, business impact, and context-dependent harms.
10. Record evidence and produce actionable findings
Every confirmed result should be reproducible and actionable. Capture at least these fields:
| Field | What to record |
|---|---|
| Identifier | Unique finding or test-case ID and date. |
| Setup and context | Environment, model and application versions, permissions, data, and configuration. |
| Scenario or input sequence | Prompts, files, retrieved content, tool steps, and relevant conversation history. |
| Output and traces | Model output, tool responses, logs, traces, screenshots, or other supporting evidence. |
| Affected layer | Model, prompt, application, RAG, agent, tool, memory, integration, or output path. |
| Severity and impact | Likelihood, technical effect, customer or business impact, and relevant legal or reputational consequences. |
| Owner and status | Responsible team, remediation status, risk acceptance if applicable, and target release. |
| Retest status | Retest date, configuration, result, remaining limitations, and closure decision. |
An actionable report can include an executive summary, engagement overview, detailed findings, attack narratives for complex chains, recommendations, and supporting evidence. Describe impact in business terms as well as technical terms.
11. Remediate, regress, and retest
Closure means verifying risk reduction, not merely recording a proposed fix.
- ☐ Assign an owner and document the chosen remediation or formally accepted risk.
- ☐ Apply appropriate controls, such as guardrails, runtime controls, blocking, redaction, prompt changes, model changes, permission changes, or retrieval changes.
- ☐ Reproduce the original failure after the fix using the same setup and input sequence.
- ☐ Confirm that the prohibited outcome no longer occurs and that the fix has not introduced a material regression.
- ☐ Convert every confirmed failure into a regression case.
- ☐ Retain evidence, retest dates, configuration details, and residual limitations.
| Checkbox | Closure step | Expected evidence | Status |
|---|---|---|---|
| ☐ | Original failure reproduced | Original input, output, configuration, and trace. | Open / Done |
| ☐ | Remediation applied | Fix description, owner, version, and change record. | Open / Done |
| ☐ | Retest completed | Dated retest result showing whether the outcome reproduces. | Open / Done |
| ☐ | Regression added | Automated or repeatable case linked to the finding. | Open / Done |
12. Continue assurance through CI/CD and production
Repeatable adversarial tests should enter development and release workflows where appropriate.
- ☐ Run regression suites when prompts, models, retrieval, data, permissions, or application code changes.
- ☐ Use release gates or severity thresholds when the organization has defined them.
- ☐ Repeat deeper campaigns after material model, prompt, retrieval, data, or architecture changes.
- ☐ Monitor for prompt-injection or jailbreak signals, sensitive-data exposure, anomalous behavior, and failed controls where appropriate.
- ☐ Maintain detection, blocking, redaction, escalation, and incident-response procedures for production findings.
- ☐ Schedule recurring assessments rather than treating deployment approval as permanent assurance.
Production assurance should preserve evidence of monitored signals, alerts, blocked or redacted outputs, escalations, and review decisions. Runtime controls complement red teaming; they do not replace authorized testing or fix verification.
13. Map the program to frameworks and choose implementation options
Findings may be mapped to OWASP, the NIST AI RMF, or MITRE ATLAS where useful. Record the mapping alongside the affected layer, risk, remediation, and retest evidence to support consistent coverage and governance communication.
Implementation options include tools such as Promptfoo, PyRIT, or DeepTeam. Select tools according to the system, vulnerability coverage, multi-turn and agent support, observability, test-data controls, automation needs, and CI/CD integration. These are options, not mandatory requirements, and no tool or checklist provides complete coverage by itself.
Final LLM red-teaming checklist
Document reproducible findings, prioritize them according to impact and exposure, remediate them, convert confirmed failures into regression tests, retest before release, and repeat testing after material changes to the model, prompts, retrieval, data, permissions, or architecture.
A checklist or tool can structure coverage, but it does not prove that an LLM system is completely secure or safe. Assurance comes from authorized testing of the assembled system, verified remediation, continuous regression, and dated retesting.